Microsoft Copilot Alternatives in 2026
Oct 19, 202614 min read
To reclaim technical autonomy and eliminate mandatory licensing overhead, enterprise teams are shifting toward unbundled AI strategies.
Why teams leave Microsoft Copilot
While the initial appeal of a built-in assistant was high, the reality of deployment (often complicated by how platforms like Activepieces are utilized to bridge disparate systems) has led to a sequestration known as the "POC Graveyard."
48.6% of enterprise AI projects remain stuck in the proof-of-concept phase, meaning nearly half of all corporate AI investments fail to deliver measurable utility to end-users.
Only 31.4% reach full production status, while 20.0% of projects are abandoned entirely, suggesting that many initiatives fail to deliver their intended value.
This low success rate forces leadership to look beyond default suite plugins to find tools that actually survive the transition from demo to daily workflow.
The hidden cost of the Microsoft 365 prerequisite
The primary financial barrier is the prerequisite licensing structure, which forces companies to pay for high-tier seat licenses before even purchasing the AI add-on.
This tax on innovation means a department wanting to use Gemini 3.8 Flash for its superior agentic speed must still maintain a baseline Microsoft ecosystem investment they may not fully utilize.
Data sovereignty and the 'black box' problem
When proprietary information is processed through a closed loop, security leads become increasingly wary of the opaque nature of data handling.
Platform's analysis puts the risk at a point where teams lose the ability to audit exactly how models like GPT-6 Astra interact with their internal knowledge base.
Without granular control over data residency and model selection, organizations risk vendor lock-in. This prevents them from switching to a more secure or cost-effective model, such as Mistral Large 4, without a total infrastructure overhaul.
Integration friction with non-Microsoft software
The "walled garden" effect limits an assistant's utility to a fraction of the modern enterprise tech stack. According to data from Assistents, the gap in native connectivity is significant:
- ERP has 45 connectors, ensuring that critical resource planning data remains isolated from the assistant.
- Support has 42 connectors, which prevents customer service agents from pulling real-time ticket history into their AI workflows.
- CRM has 38 connectors, meaning sales teams must manually bridge data between their customer databases and their drafting tools.
- Collaboration has 35 connectors, limiting the AI’s ability to parse context from diverse messaging platforms.
- HRIS has 32 connectors, which keeps sensitive personnel data locked away from automated administrative tasks.
- Finance has 28 connectors, forcing manual data entry for budget reporting and forecasting.

What is the Model Context Protocol (MCP)
The Model Context Protocol (MCP) acts as a universal bridge that standardizes how AI models interact with external data sources and software tools.
An MCP server functions as a translator, exposing local or remote resources to an AI client in a format the model can instantly understand and manipulate.
How the MCP client-server protocol works
Technically, MCP is an open standard that uses a client-server architecture to decouple the AI application from the data it needs to access. The protocol typically operates over JSON-RPC, allowing a client to query a server for specific capabilities or "tools."
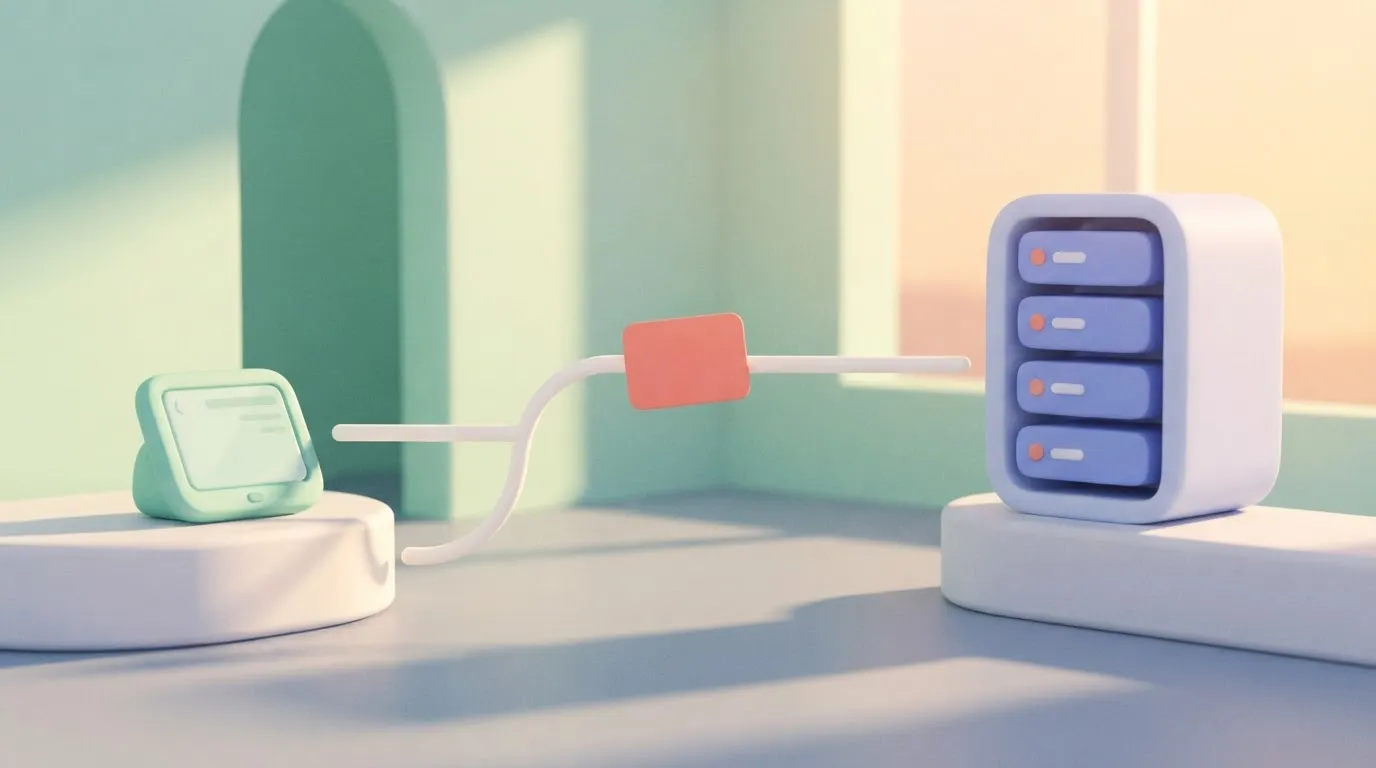
When a user asks a question, the AI client sends a request to the MCP server to fetch relevant files or execute a command.
The server responds with structured data, ensuring the model never has to guess how to interface with a specific API or database schema.
Activepieces is a per-project MCP server that makes every connected integration available to the AI as a tool. This mechanism ensures that 738+ integrations are reachable by Claude or ChatGPT without a second migration or manual export step.
Check the Integrations Framework and MCP Server documentation in the open source repo to see how these actions are exposed directly to AI clients.
The fastest way to settle a shortlist is to try one. Activepieces is free to try, no credit card.
Leading Microsoft Copilot alternatives compared for 2026
Unbundling allows organizations to select tools based on performance benchmarks rather than suite compatibility. The following comparison highlights how standalone enterprise platforms differentiate their offerings.
| Primary Strength | Pricing | Ideal User Profile |
|---|---|---|
| Claude for Enterprise | Advanced reasoning and long-horizon agentic work via Claude Fable 5.1. | Custom quotes based on seat count and usage. |
| Google Gemini | Deep integration with Google Workspace and massive context handling via Gemini 3.8 Flash. | Tiered per-user monthly subscriptions for Business and Enterprise. |
| OpenAI for Business | Access to GPT-6 Astra for complex reasoning and a vast ecosystem of custom GPTs. | Enterprise-grade pricing starting above the $20 / month Plus tier. |
| Perplexity Pages | Real-time information discovery and structured report generation from live web data. | Monthly per-user fees with enterprise administrative controls. |
Prices and plan limits checked against docs.claude.com and openai.com and gemini.google on October 7, 2026.
Unbundling your AI stack for independence
True independence requires moving beyond simple SaaS alternatives to a modular architecture. By separating the user interface, the reasoning model, and the data storage, teams can build a private AI assistant that remains entirely under their own control.
This strategy utilizes open-source frameworks to connect private data to various LLMs without locking into a single vendor's roadmap. It allows for the use of local models or specialized APIs that offer better privacy and lower latency than general-purpose bundled assistants.
Self-hosting for maximum data control
Self-hosting the AI orchestration layer provides the highest level of security. Organizations can deploy their automation and intelligence tools on internal servers or private clouds, ensuring that no data ever leaves the corporate perimeter for model training.
This approach eliminates the "black box" problem by providing full visibility into every data request. It is the preferred method for industries with strict regulatory requirements that cannot risk the opaque data handling practices of large public AI providers.
Microsoft Copilot requires a base subscription to Microsoft 365, meaning the AI cost is always an additive layer atop an existing seat license.
For a startup or a lean enterprise, this creates a "suite tax" where they must pay for Office apps they may not use just to access the assistant.
In contrast, standalone tools like OpenAI offer a Free plan at $0 / month, allowing teams to validate a model's utility before committing to the Pro or Enterprise tiers.
By using Claude for Enterprise, administrators gain granular control over data retention policies and can ensure that sensitive intellectual property is not used to train future iterations of public models.
Bundled AI assistants often prioritize internal ecosystem convenience over transparent data routing, making it difficult to audit exactly how information flows between documents and the model.
This isolation is a prerequisite for legal and healthcare sectors where regulatory compliance mandates strict data boundaries.
Copilot is designed to be "Office-first," which often results in degraded performance when interacting with external CRMs, project management tools, or specialized databases.
Standalone enterprise AI platforms treat every integration as a first-class citizen, providing robust APIs that allow a model like Gemini 3.8 Flash to trigger actions across a diverse software stack without favoring a specific vendor.

This prevents the "walled garden" effect. The AI is a flexible bridge between tools rather than a siloed feature of a single suite.
Orchestrating custom AI workflows with Activepieces
Building modular AI logic
This modular approach allows you to swap models based on the specific requirements of a task. Activepieces provides an MIT-licensed core that connects disparate AI models to your existing software stack, allowing for self-hosted deployments that avoid the rigid constraints of a single-vendor ecosystem.
By self-hosting the platform, you maintain absolute sovereignty over the data flowing between your communication channels and your intelligence engines.
Routing tasks to specialized models
A platform that resells you a model has already decided your AI strategy and priced it for you. Activepieces runs whatever model you choose on your own provider key, so model spend lands on your own account at your own rate.
A platform that resells you a model has already decided your AI strategy and priced it for you.
MoneyGram and FundingSocieties run this in production to maintain control over their model selection and spend across 738+ integrations.
Scaling agentic AI workflows beyond chat
The primary advantage for a scaling organization is the ability to build "agentic" workflows that do not require a human to prompt the assistant inside a chat interface.
For example, a new lead in a CRM can automatically trigger a research sequence where Gemini Deep Research analyzes the prospect’s industry filings.
Claude Sonnet 5.5 then formats the resulting brief and pushes it directly into a private Slack channel.
Maintaining extensible frameworks
Because Activepieces is built on an extensible framework, you are not waiting for a corporate roadmap to support new tools.
You can write custom integrations in TypeScript to connect to proprietary internal APIs so your AI strategy remains integrated with your unique business logic.
This decoupling ensures that if a specific model provider changes their pricing or terms, you simply update one node in your workflow rather than rebuilding your entire operational infrastructure.
By unifying its entire library of connectors into a standardized framework, the platform ensures that every integration functions natively as an agent tool via the Model Context Protocol.
Activepieces is the better fit for developers who require a library of pieces that are immediately compatible with AI agents without manual wrapping. This architectural alignment between standard automation and agentic capabilities makes it the superior option for building extensible, tool-enabled AI workflows.
Reading a table only gets you so far. Build the same workflow in Activepieces and compare it yourself.
Build private AI assistants with Claude
Building a private AI assistant requires decoupling the reasoning engine from the data layer to ensure that proprietary information remains under internal governance.
By utilizing the Claude Sonnet 5.5 API for logic and Pinecone for memory, an organization can replicate the retrieval capabilities of Microsoft Copilot while maintaining granular control over data residency and model versions.
The following steps outline the architecture for this deployment:
- Provision Claude Sonnet 5.5 API key.
- Initialize Pinecone vector database.
- Index internal documentation.
- Connect RAG pipeline to the LLM.
Connecting your data sources to a vector database
The effectiveness of a private assistant depends on its ability to search through unstructured data, which requires converting that text into mathematical vectors. Pinecone, a managed vector database, is the long-term memory for the assistant by storing these embeddings.
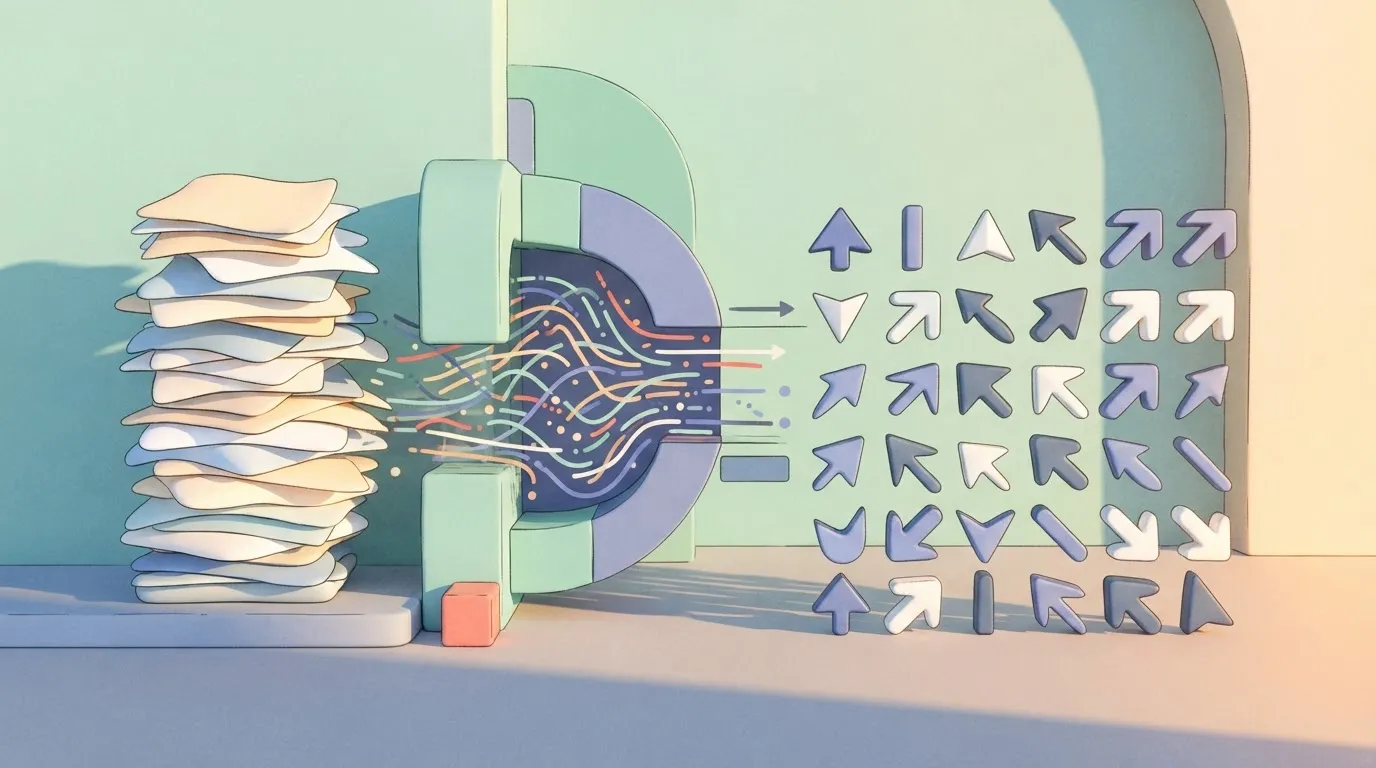
When a user asks a question, the system searches Pinecone for the most relevant snippets of information and passes them to Claude Sonnet 5.5 as context.
This prevents the model from hallucinating, as its "truth" is restricted to the indexed files.
Configuring the AI system prompt for brand voice
Once the data pipeline is active, the system prompt defines the constraints and personality of the assistant to ensure it aligns with corporate communication standards.
Unlike the rigid personas in bundled suites, a custom system prompt for Claude Sonnet 5.5 can include specific instructions on formatting, technical depth, and prohibited topics.
Every generated response follows a consistent logic.
Testing AI response accuracy in a sandbox
Before deploying the assistant, it must be validated in an isolated environment to identify potential leakage or incorrect data retrieval.
A sandbox allows developers to run batch queries against the Pinecone index to verify that the RAG pipeline is pulling the correct documentation.
If the assistant provides an inaccurate answer, the team can adjust the "top-k" parameters or refine the data chunks within the database.
Automating AI actions with Gemini across your stack
Proactive AI integration shifts the assistant from a passive chat interface into an autonomous operator that monitors your business events in real-time.
By connecting reasoning models like Gemini 3.8 Flash to your existing communication and project management layers, you eliminate the "human-in-the-loop" bottleneck for routine data processing.
| Trigger Event | AI Action |
|---|---|
| New lead created in Salesforce | Research prospect's recent funding and draft personalized outreach. |
| High-priority ticket in Zendesk | Trigger sentiment analysis to determine if executive escalation is required. |
| Negative sentiment detected in Slack | Summarize friction point for the product team. |
| Unresolved task in Jira | Identify blockers based on recent developer comments. |
Setting up the Slack 'Mention' trigger
Configuring a Slack "Mention" trigger ensures your AI assistant only consumes relevant context. In the Slack API dashboard, you must enable Event Subscriptions and point the Request URL to your automation middleware.
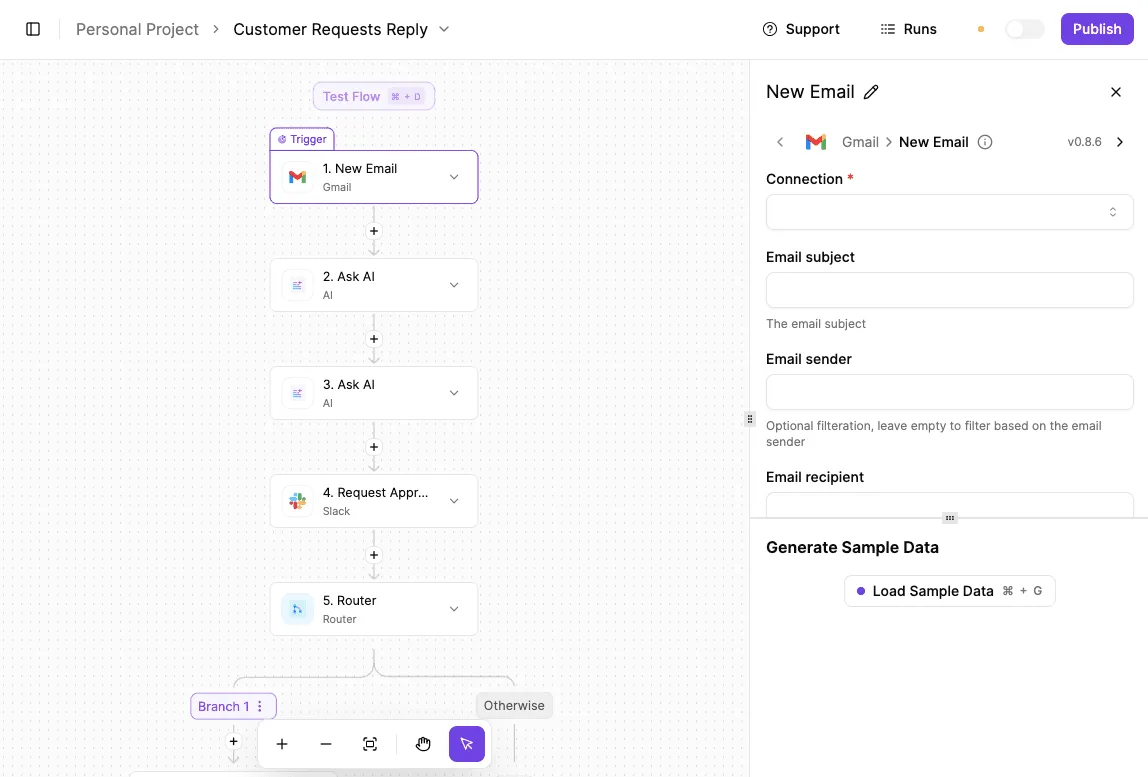
This creates a filtered stream where the AI only activates when specifically called, preventing unnecessary token spend. Once the connection is verified, you can pass the thread history to a model like Claude Sonnet 5.5 to maintain conversation continuity.
Mapping AI outputs to email drafts or CRM updates
Directly injecting AI responses into production databases is a high-risk strategy, so you should map outputs to "Draft" or "Pending" states first.
For instance, when using the Google Gemini free tier, which offers 15 GB of storage across Gmail and Drive for $0/month, you can program the AI to write a response directly into a Gmail draft.
This allows a human to perform a final sanity check. Similarly, CRM updates should be mapped to temporary fields or "Notes" sections rather than overwriting primary contact data.
Deploying the live workflow for your team
Deployment involves moving from a single-user API key to a shared service account to ensure the workflow doesn't break when a team member changes their password.
You must set up error-handling paths. If Gemini 3.8 Flash hits a rate limit, the workflow should post a "System Busy" message in Slack rather than failing silently.
Once the logic is robust, you can roll it out to a pilot group.
Frequently asked questions about AI assistant migration
Direct data control is the primary driver for unbundling, as it eliminates the requirement to send internal documents to a shared public cloud for processing.
By deploying models like Mistral Large 4 within a Virtual Private Cloud (VPC), your data stays behind your firewall; sensitive intellectual property never trains a third-party model.
Can I keep my data in my own VPC when switching?
Migration to a decoupled AI architecture is a way to achieve complete network isolation because you control the inference endpoint.
When you use a private instance of a model through a cloud provider’s dedicated environment, the traffic stays within your defined security perimeter, so your compliance team does not need to audit new external data sub-processors.
Do these alternatives support Excel-style data analysis?
Advanced reasoning models perform structured data manipulation by writing and executing sandboxed code.
Gemini 3.8 Flash executes Python scripts against uploaded spreadsheets to generate pivot tables and trend visualizations. Claude Opus 5.5 analyzes complex financial statements to identify accounting anomalies across multiple tabs.
GPT-6 Astra cleans messy CSV exports by identifying and correcting formatting inconsistencies automatically.
How much cheaper are these options than Copilot?
By routing simple tasks to a low-latency model like DeepSeek-V4.1-Flash-1017 and reserving high-reasoning models like GPT-6.1 Sol for complex engineering work, you align your costs directly with the value generated.
Unbundling replaces flat-rate per-user licensing with consumption-based billing, which prevents paying for employees who only use AI once a month.
This granular control means your monthly invoice reflects actual API calls rather than a fixed seat count that remains static regardless of usage.
Which alternative has the best mobile application?
The most effective mobile experience depends on whether your priority is voice interaction or document review on the go.
GPT-Live 1 provides the most fluid verbal interface, allowing field workers to dictate reports hands-free. Claude Sonnet 5.5 is a highly responsive mobile interface for reviewing long-form technical documentation during commutes.
Gemini 3.5 Live Translate enables real-time speech-to-speech communication, which is essential for international teams conducting site visits.
Related reading
References
Still comparing
The fastest way to settle it is to build something.
Open source under MIT, so you can self-host the same thing later.
Start free Talk to sales