Qwen3.8 Flash Next Launch: Specs, Benchmarks, and License
Oct 20, 20269 min read
The model enables developers to build more responsive agents, which is particularly useful when deploying complex logic through Activepieces to automate repetitive business tasks.
These benchmarks suggest that the gap between high-reasoning capabilities and instantaneous execution is closing, allowing for seamless integration into high-volume data pipelines without the traditional performance bottlenecks.
This release moves the industry closer to a state where intelligence is a background utility rather than a metered luxury.
Qwen3.8 Flash Next release date and details
When the Qwen Team at Alibaba Group released Qwen3.8 Flash Next in August 2026, they delivered an open-weight Causal Language Model with an integrated Vision Encoder.
As an experimental preview of the architecture that'll underpin Qwen4, this specific release allows you to test next-generation routing logic before the full generational shift.
A Sparse Mixture-of-Experts (MoE) design replaces the monolithic structures of previous iterations to maintain high performance while reducing the computational load per token.
Across its 48 layers, the Sparse MoE architecture includes 512 experts, of which only 10 routed experts (plus one shared) activate for any single token path.
Simple classification tasks no longer consume the same hardware resources as complex visual reasoning because of this granular activation.
It prevents the "compute tax" usually associated with multi-modal models.
Targeting the high-frequency automation niche
These decisions include sorting thousands of incoming support tickets or validating visual receipts.
Once a connector is configured in Activepieces, it functions simultaneously as a step in a structured flow and a tool schema on a per-project MCP server.
Activepieces added Qwen as a supported AI provider, alongside xAI, DeepSeek, Z.ai, MiniMax and Moonshot, all speaking the OpenAI wire format.
Check the Integrations Framework in the open-source repo to see how the same action code powers both deterministic flows and agentic tools.
The industry now categorizes these models as "commodity" intelligence.
For vision-integrated "thinking" modes at a low cost-per-token, DeepSeek-V4.1-Flash is the alternative. DeepSeek-V4.1-Flash occupies the open-weight tier, offering a bridge for your team if you require the privacy of self-hosting with the speed of a flash-class API.
When intelligence is fast and inexpensive, the bottleneck shifts from the cost of the model to the reliability of the audit trail. Multi-step agentic workflows benefit from significantly reduced long-context latency, which matters as agentic workloads increasingly dominate real-world usage.
Measure performance gains from Alibaba Cloud benchmarks
Commodity status is achieved by Qwen3.8 Flash Next by maintaining high-density reasoning across a 262,144-token native context window. This capacity keeps multi-step audit logs coherent without the truncation risks found in smaller models.
200 pages of ledger data can be ingested in a single pass by a controller using this capacity, as verified by MindStudio.
GPT-6 Luna has a 1,050,000-token context window with 128,000 max output tokens, while the older Llama 3.1 8B was capped at 128,000 tokens. They force a fragmented and less reliable analysis of long-tail financial anomalies.
Qwen3.8 Flash Next long-context throughput performance
Deep context is processed by Qwen3.8 Flash Next, enabling continuous monitoring.
The Qwen3.8-Flash-Next architecture natively supports 262,144 tokens and is extensible up to 1,000,000, a middle ground for localized deployments. It requires less overhead for high-frequency reconciliation.
| Model | Context Window (Tokens) | Operational Impact |
|---|---|---|
| Gemini 3.8 Flash | 1,000,000 | Supports the ingestion of an entire fiscal year's worth of granular transaction data. |
| Qwen3.8 Flash Next | 262,144 | Sufficient room for a full quarterly audit trail including all supporting metadata. |
| GPT-6 Luna | 1,050,000 | Fits very large document sets in one pass, reducing the need for "chunking" strategies. |
| Llama 3.1 8B | 128,000 | Limits the model to single-department reviews rather than cross-functional oversight. |
Prices and plan limits checked against huggingface.co and huggingface.co and huggingface.co and github.com on October 9, 2026.
GSQ-RCO-GGUF quantization for Qwen3.8 Flash Next
The GSQ-RCO-GGUF quantization format significantly reduces the hardware barrier for running Qwen3.8 Flash Next. Your firm can run complex reasoning on a well-equipped workstation, though heavier quantization trades away some precision.
This allows an auditor to run a private instance on a well-equipped workstation rather than relying on unverified third-party cloud environments.
Local execution interfaces for open weights
Running these GGUF files locally requires a dedicated inference engine to load the model into your system memory. Tools like LM Studio provide a graphical interface that simplifies the process for users accustomed to web-based chat applications.
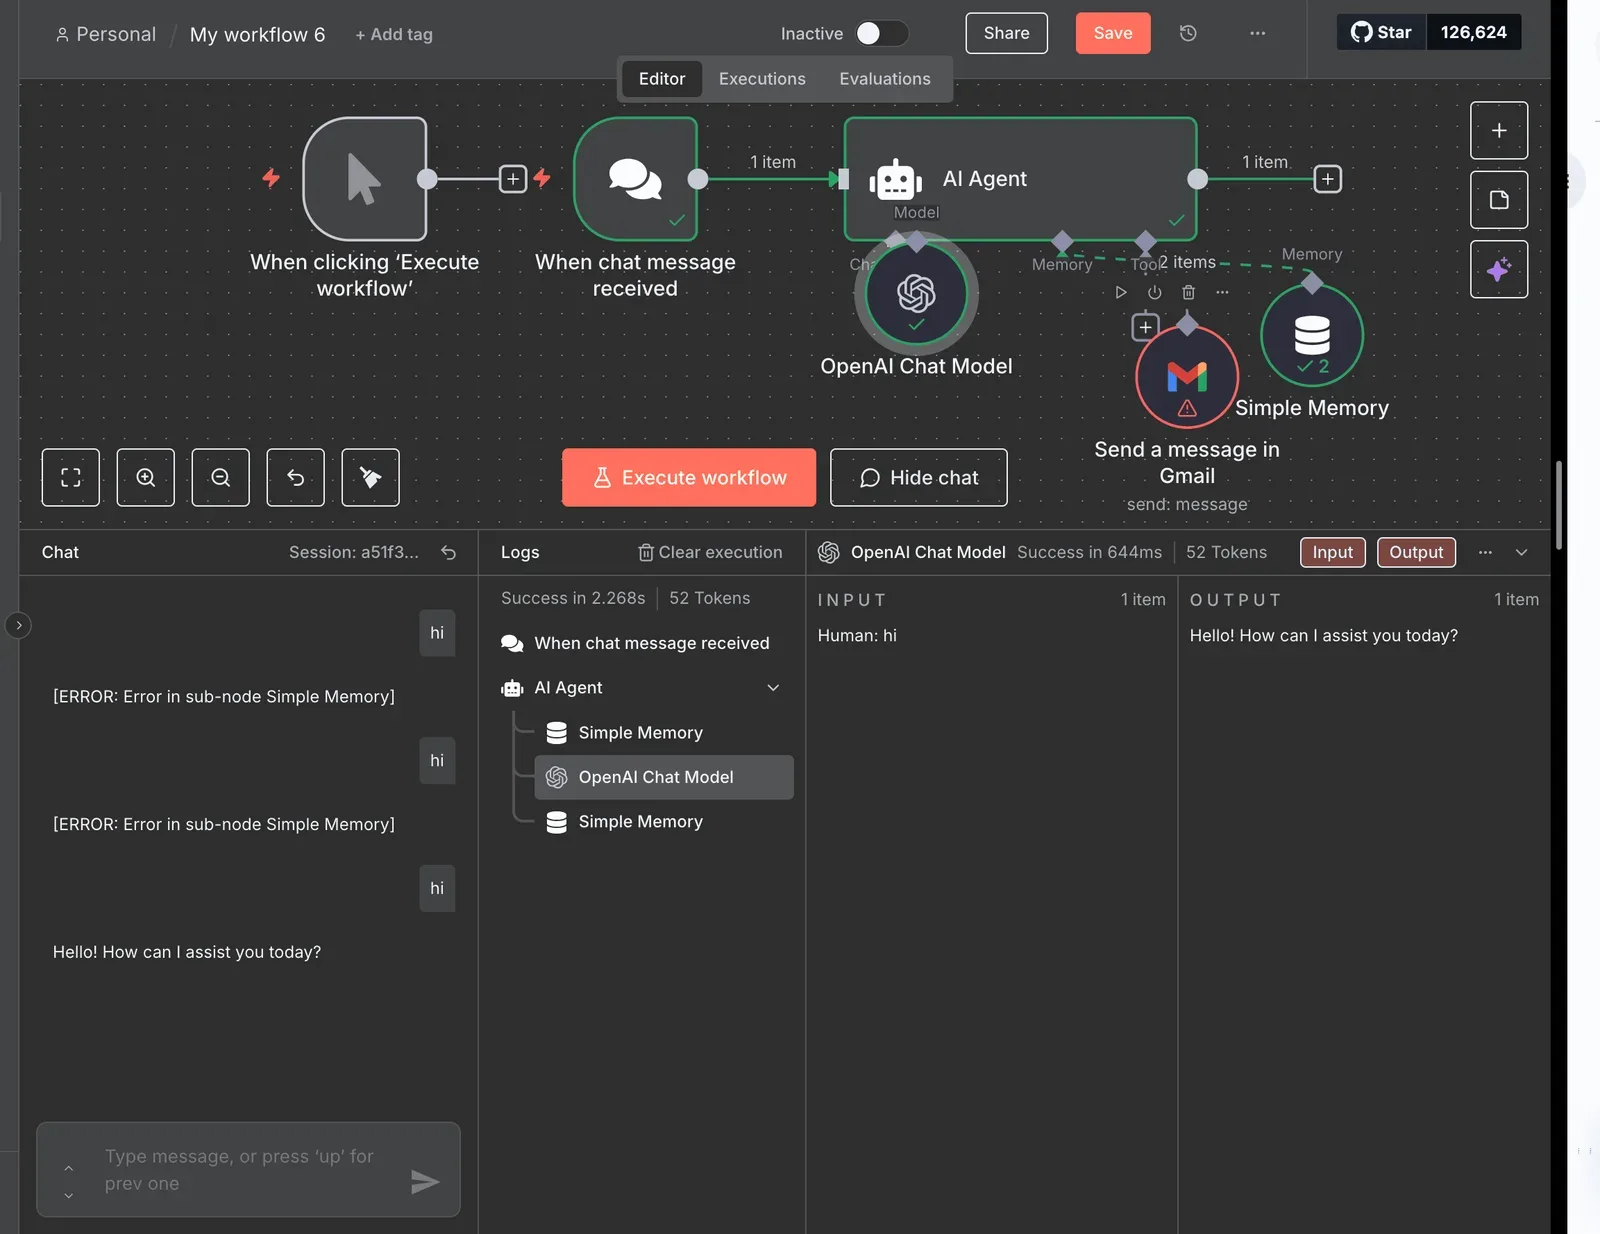
For automated environments, Ollama offers a command-line approach that manages model versions and serves them as a local API. Enterprise-scale local deployments often utilize vLLM to maximize throughput across multiple GPUs, ensuring the commodity intelligence remains responsive under heavy load.
| Quantization Level | File Size (GB) | VRAM for 8K Context (GB) |
|---|---|---|
| 6-bit (GSQ) | — | — |
| IQ3_S (GSQ) | 83.6 | — |
High-fidelity intelligence becomes available at the edge of the network because of this reduction in resource consumption. It depends on the available local memory of your workstation.
Connect DeepSeek-V4.1-Flash to local inference servers
Activepieces includes Qwen as a supported AI provider for use within your automation flows. When using the OpenAI or LLM integration, you can bypass cloud endpoints by entering your local server address in the Base URL field.
This configuration ensures that sensitive data never leaves your infrastructure while maintaining the same workflow logic used for cloud-based models.
This setup allows the automation engine to treat your local GPU cluster as a private, high-speed API provider.
Everything below works on Activepieces' free plan. Start without code or a credit card.
Deploying DeepSeek-V4.1-Flash within Activepieces workflows today
High-frequency model calls translate into verifiable business actions through this platform. By standardizing the communication layer between disparate software services, the platform eliminates the need for bespoke integration code that typically obscures the audit trail.
Updating the openrouter integration connector
Activepieces added Qwen as one of six new AI providers that speak the OpenAI wire format. This is the modular connector Activepieces uses to bridge internal workflows with external model providers.
A platform that resells you a model has already decided your AI strategy for you. Activepieces added Qwen as a supported AI provider, communicating via the OpenAI wire format.
Check the Bring-Your-Own-Key availability on the pricing page to see how this preserves your ability to switch providers as rates shift.
MoneyGram and FundingSocieties run Activepieces in production to maintain this level of control over their automation infrastructure.
Activepieces has added Qwen as an AI provider, using the OpenAI wire format. This allows a controller to redirect traffic to the most cost-efficient provider as soon as market rates shift.
Connecting the model to business apps without code
Operationalizing commodity intelligence requires a direct link between the model’s reasoning and the databases where records live.
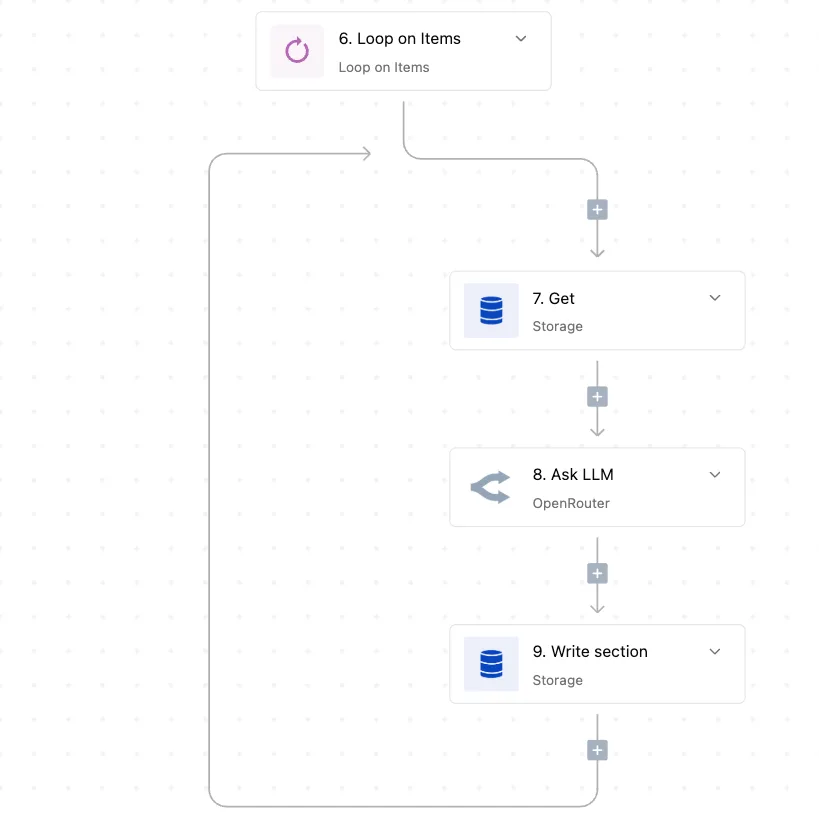
Every automated step is triggered by a specific event and logged for review.
When you select the "new flavor created" trigger within the Ice-cream integration, you establish the starting point for the automation. The interface confirms the successful handshake between a custom business event and the model's processing environment.
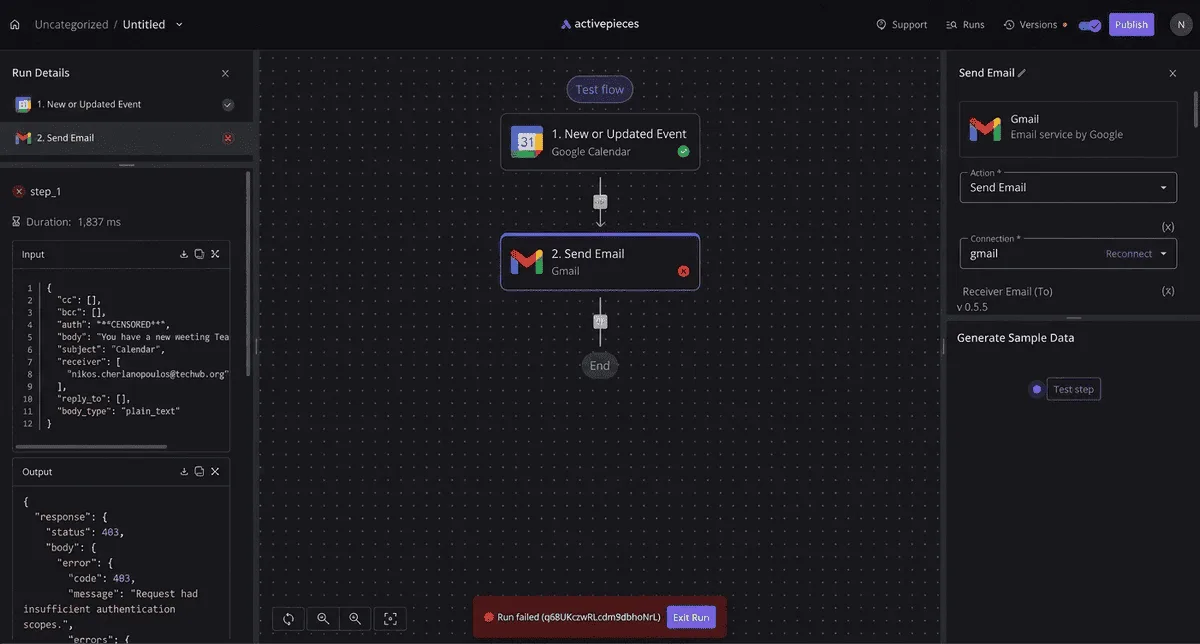
Downstream tasks like inventory routing or descriptive tagging are ready once you verify the connection and load sample data. This no-code approach to model deployment secures the workflow through three distinct layers.
- The Trigger layer defines the exact business event that initiates a model call.
- The Connection layer manages encrypted credentials for the AI provider.
- The Data layer is a sample output for manual verification before the flow is activated.
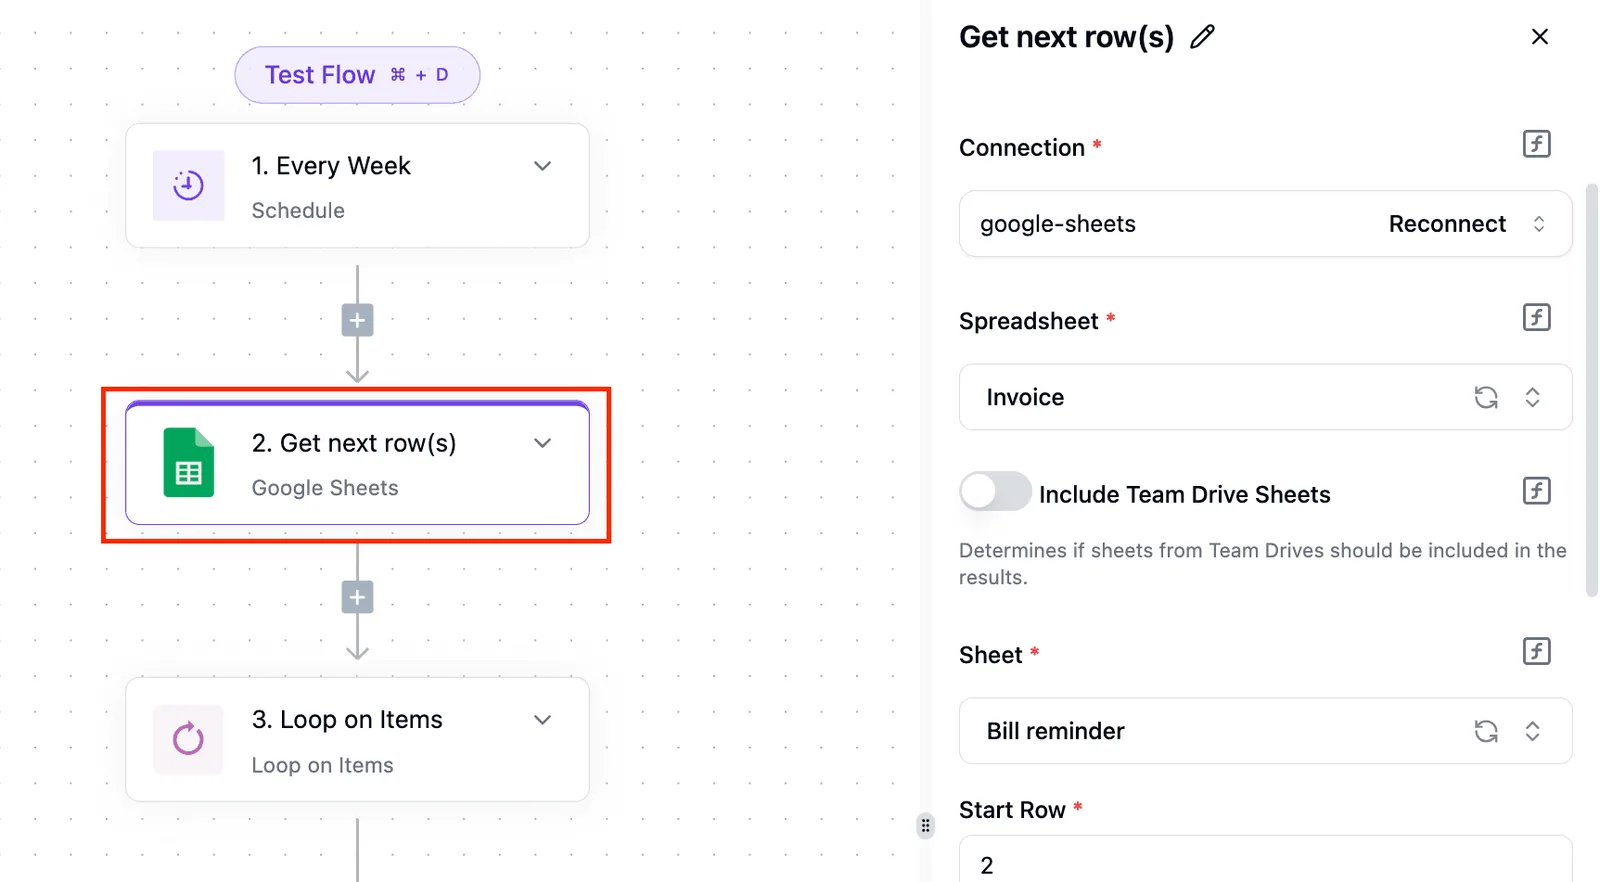
You can audit your automation logic as easily as you would a physical ledger by moving these steps into a managed canvas.
Compare DeepSeek-V4.1-Flash against standard models
It allows controllers to authorize thousands of autonomous verification steps without breaching monthly operational budgets. This shift transforms model selection from a performance trade-off into a standard procurement decision based on unit cost.
Cost per million tokens analysis
The marginal cost of each reasoning step determines the fiscal viability of an automated audit trail.
The marginal cost of each reasoning step determines the fiscal viability of an automated audit trail.
DeepSeek-V4.1-Flash is a vision-capable model that's a low-cost entry point for multimodal verification, such as comparing physical receipts against digital ledger entries. GPT-6 Luna is OpenAI's specific tier for cost-sensitive workloads. This tier prevents high-volume routing from consuming the credits reserved for frontier-class reasoning.
Latency reductions for multi-step agents
The difference between a real-time compliance check and a post-hoc error report is the speed of the multi-step workflow.
When an agent must call an external database, verify the credentials, and then format a response, the cumulative delay of each token can stall a customer-facing process.
Reduced long-context latency enables agents to complete complex loops before a user session times out.
Higher throughput ensures that the "thinking time" of an agent doesn't become the primary bottleneck in a synchronized data pipeline.
Develop DeepSeek series for local LLM deployment
High-reasoning capabilities move from centralized cloud providers to controlled, internal infrastructure under the DeepSeek roadmap. This shift allows compliance officers to approve agentic workflows that were previously blocked due to data residency requirements or the unpredictable latency of public APIs.
By moving toward a diversified model ecosystem, the series is a tiered approach to intelligence that matches specific audit requirements to the appropriate compute expenditure.
With the native 262,144-token window extensible up to 1M tokens, entire technical manuals or multi-year ledger histories can be ingested.
This means the model can maintain state across exhaustive verification cycles. Local deployment via GGUF/Unsloth enables your team to run models on consumer-grade or mid-range enterprise hardware. Running it locally ties the cost of each inference to electricity and hardware depreciation rather than a per-token fee.
With the addition of native visual processing, the model can interpret unstructured data sources like scanned invoices or handwritten logs, bringing physical-world documentation into the automated audit trail.