GLM 5.3 Prime: Pricing, Benchmarks & Context Window

Oct 23, 202610 min read
As we move through the third quarter of 2026, the competitive landscape for automated reasoning has shifted from basic text generation to deep multimodal synthesis.
The current benchmarks for enterprise automation, which often rely on orchestration layers like Activepieces to manage complex workflows, are no longer defined by the legacy models of the early 2020s, but by a new generation of high-reasoning engines.
GLM-5.3 in the 2026 AI market
GLM 5.3 market outlook for late 2026
GLM-5.3 Prime is a high-reasoning model focused on coding and cybersecurity, built for enterprise automations. Its gains come entirely from post-training on those tasks rather than retraining the base model.
The data and comparisons provided in this analysis reflect the state of the market as of August 2026. At this stage, the industry has moved beyond the experimental phase of agentic workflows into a period of massive scale and economic optimization.

GLM-5.3 Prime represents a shift toward high-reasoning coding- and cybersecurity-focused models that allow you to automate complex textual workflows.
By concentrating its post-training on coding and cyber-security tasks rather than retraining the base model itself, the model's gains come entirely from that post-training work.
GLM-5.3 multimodal text and vision architecture
To process linguistic inputs for coding and cyber-security tasks, the model utilizes a single transformer backbone. The following mechanisms interpret spatial data from images with the same reasoning depth as text:
How GLM-5.3 processes text and images together
The transformer backbone functions as a shared neural highway where text tokens and visual patches are treated as equivalent units of information.
Beyond text, the model applies configurable thinking-effort levels—low, high, and max—to reason step-by-step over text tokens.
This allows the reasoning engine to calculate the relationship between different sections of a lengthy contract entirely from its text content.
Because the model's post-training builds directly on its base model, it does not have to relearn its underlying reasoning from scratch.
This shared foundation ensures that the high-level reasoning used to solve a logic puzzle is the exact same logic applied to identifying a vulnerability in source code.
The result is a model that understands spatial context, such as the layout of a complex dashboard, without losing the semantic nuance of the labels within it.
This unified approach prevents the context loss typically seen when bridging disparate vision and language models. Internal evaluations via OpenRouter tested the model's ability to extract fields from invoices and sort support tickets against a known answer key.
The rapid adoption of this architecture by leading open-source automation platforms and other workflow providers suggests a market pivot toward models that can handle "eyes-on" tasks.
The timeline below illustrates the model's rollout.
- August 24, 2026: Activepieces added Z.ai (GLM) as a first-class AI provider, one of six new providers using the OpenAI wire format.
Following this general availability, you can now deploy the model across various cloud environments without waiting for regional rollouts.
Availability via the BigModel API
Enterprise access is managed by the BigModel API, which has the standardized endpoints necessary for integrating the model into your existing software stacks. This direct access allows you to bypass the complexities of self-hosting while maintaining the ability to process large-scale multimodal batches.
Global requests are supported by the current API infrastructure.
The API also supports structured output formats. Your databases or CRM systems can receive data directly from the model without additional parsing logic.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Large-scale context handling for complex data workflows
This allows you to process thousands of pages of technical documentation without the loss of detail caused by vector database chunking.
Z notes that compared to Claude Sonnet 5.5 (which has a 200,000-token limit) GLM-5.3 Prime allows for five times more data per prompt. This removes the need for multi-turn state management.
Mistral Large 3, at 128,000 tokens, leaves you with 87% less room per request than GLM-5.3 Prime according to Explainx, which means your model is operating with a significantly narrower context window.
This risks missing critical edge cases in complex logic. The following table demonstrates how these limits dictate the scale of data an automated agent can "see" at once before it must rely on external memory.
| Model | Context Window | Max Output Limit |
|---|---|---|
| GLM-5.3 Prime | — | — |
| GPT-6 Luna | 1,050,000 tokens | Unknown |
| Claude Sonnet 5.5 | 1M tokens | Unknown |
| Mistral Large 3 | 128,000 tokens | Unknown |
Prices and plan limits checked against z.ai and github.com and openrouter.ai on September 30, 2026.
The bottleneck moves from how much data a model can hold to how much it can actually synthesize in a single pass.
This eliminates the logic drift that occurs when stitching multiple smaller outputs together.
GLM 5.3 adoption and usage on OpenRouter
GLM 5.3 pricing versus other AI models
On OpenRouter, a unified interface for accessing diverse LLMs, GLM 5.3 Flash currently commands 20.94% of total token volume.
This signals that the market is weighing different cost and performance trade-offs as new providers emerge.
DeepSeek V4.1 had followed this dominance at 17.6% in that period, trailing the industry leaders in total capacity, which meant the model struggled to compete with the scale of top-tier platforms.
This establishes a trend where high-reasoning models from specialized labs displace generalist giants in your automated pipelines. The shift is most evident when comparing these figures to established Western flagships:
Anthropic models represent 12.3% of volume. This suggests that while their reasoning is respected, their higher cost per million tokens limits their use in your high-frequency background tasks.
GPT-6 Luna holds 8.53% of volume.
Nemotron 3, the enterprise-focused model from NVIDIA, accounts for 5.67%, reflecting a niche but stable footprint in specialized corporate environments.
This suggests that these users prioritize specific architectural integration over the broader market trends. This distribution of traffic confirms that the "GPT-first" default is eroding.
Intelligence is now a high-volume commodity.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
Deploying GLM-5.3 Prime via Activepieces
Connecting GLM-5.3 Prime to your existing business logic requires only a standard API handshake within an automation builder.
** Intelligence is now a high-volume commodity.
The integration is facilitated by a 2026-08-24 update to Activepieces, an open-source workflow automation platform, which added Z.ai (GLM) as an AI provider.
Every connector is an agent tool; once an integration is configured in Activepieces, it is instantly available as a tool schema on a per-project MCP server for any agentic client to call.
To establish a secure handshake between your automation server and the model endpoint, the implementation process follows a linear path:
- Open the automation dashboard.
- Select the Z.ai or Avian provider.
- Input the Z-ai API key.
- Select the Z.ai (GLM) provider from the model dropdown.
Once the connection is live, you can deploy the model across several high-utility business tasks. Completing these steps creates a persistent link, allowing the model to function as a decision-making node within any triggered flow.
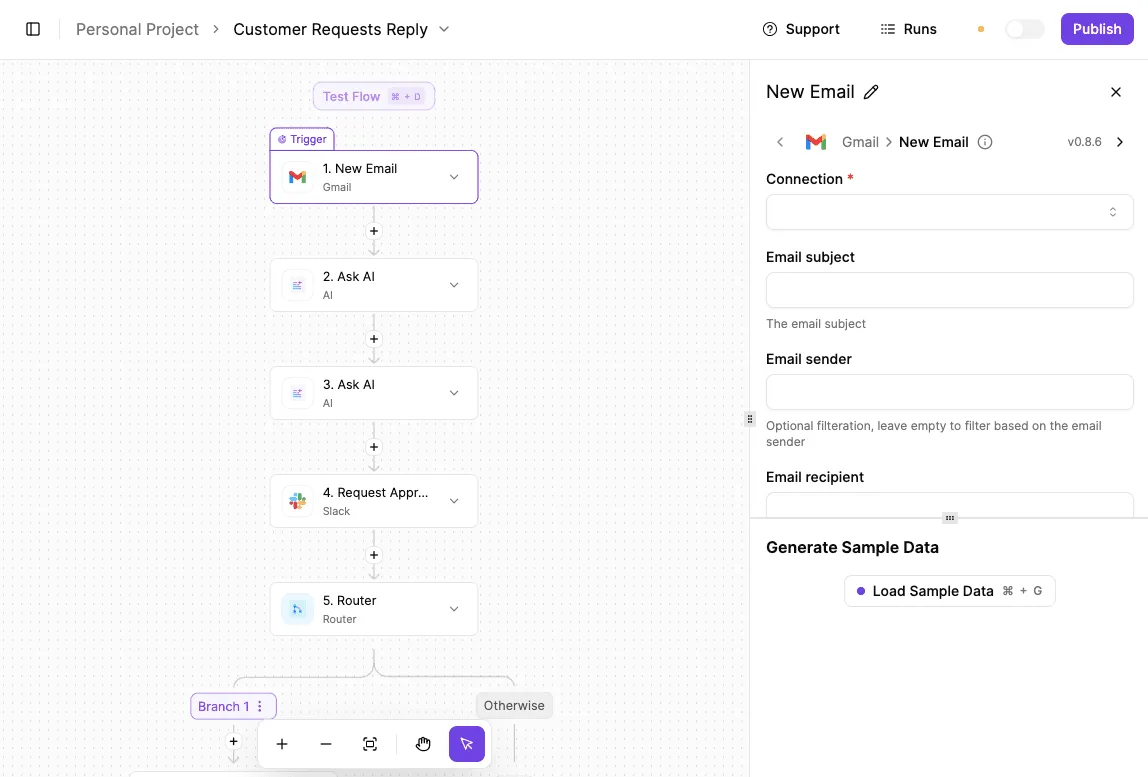
Automated data processing tasks
GLM-5.3 Prime is a translation layer between unstructured text data and formatted JSON. Your accounting software receives clean inputs without manual entry.
By processing raw text extracted from PDF files, the model identifies specific fields like line-item totals and tax IDs so that the data can be mapped directly into your database.
The model evaluates incoming support tickets or leads based on complex criteria to determine the appropriate department for escalation.
It can distinguish between a technical bug report and a billing inquiry, so that high-priority issues reach a human agent.
For legal or technical documentation, the model distills lengthy texts into actionable bullet points for your executive review.
This reduces the time spent on initial reading so that your decision-makers can focus on the implications of the content rather than the volume of the prose.
Cost and speed impact for high-volume AI automations
Balancing reasoning and overhead
GLM-5.3 Prime's points-based pricing, with off-peak calls costing half of standard points, is designed for sustained agentic workflows.
When you're deploying complex automations, the primary financial drain isn't the initial prompt but the recursive overhead of multi-step reasoning.
Z.ai has positioned this model to mitigate the "reasoning tax" that typically accumulates when a system must verify its own logic across thousands of calls.
The economic viability of these models depends on three specific performance vectors:
The model handles frontier-class coding and cyber-security tasks, reflecting its design as a frontier coding model with emergent cyber capabilities.
Your automated pipelines don't stall during complex logic gates. A large context window enables massive data ingestion in a single pass.
This means it can process very large inputs in a single pass rather than splitting them into multiple chunks.
High-precision instruction following reduces the frequency of retries, so every dollar you spend on tokens results in a usable completion rather than a discarded error.
The obvious answer for depth is a flagship model like GPT-6 Astra, but its cost per million tokens can quickly outpace the margins of your standard SaaS product.
Monitor future Zhipu AI ecosystem developments
Zhipu AI is transitioning from a specialized regional provider to a global infrastructure contender by synchronizing its hardware capabilities with developer-facing customization tools.
While flagship models like GPT-6 Astra maintain a lead in raw logic, the utility of the GLM architecture for your specific business logic depends on how quickly the ecosystem matures beyond its current general-purpose state.
The roadmap focuses on lowering the barrier for your specialized deployments. For your global teams, the 5.3 architecture has so far cost more per task than lower-cost alternatives, so it may not translate into the production savings you'd expect.
Tracking these three technical milestones will signal when the ecosystem is ready for your large-scale migration:
Fine-tuning for the 5.3 architecture allows you to lock in specific brand voices or proprietary data structures.
The model functions as a specialized internal tool rather than a general assistant.
Frequently asked questions
GLM-5.3 Prime is a tool for your complex business automations by providing native support for tool use and high-reasoning capabilities.
Technical capabilities and regional access
Native functions and context
GLM-5.3 Prime supports native function calling, which allows the model to generate structured JSON outputs that interface directly with your external software tools.
Because the model can parse its own reasoning steps into executable code, you can integrate it into agentic workflows where the model must query a database or trigger an API without your manual intervention.
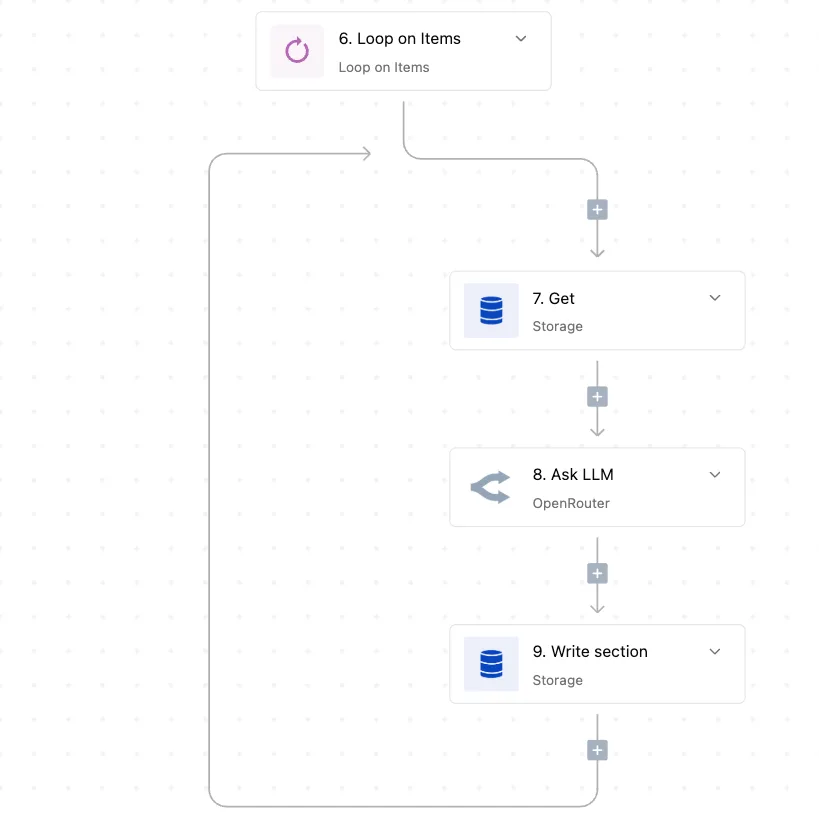
By providing a massive context window, the model enables the processing of entire technical codebases or lengthy legal documents in a single prompt.
This high capacity means you can maintain long-running conversational threads without the model losing track of earlier instructions, effectively eliminating the need for complex retrieval-augmented generation (RAG) architectures for your mid-sized datasets.
GLM-5.3 Prime is positioned as an alternative to GPT-6 Luna for AI-driven automation tasks.
In practice, high-throughput applications may find that GPT-series alternatives run at a lower per-task cost, so budgets should be planned with that difference in mind.
If you're operating in strictly regulated jurisdictions, you must verify your local data residency requirements.
This ensures that your sensitive corporate information remains within the necessary geographic boundaries to meet compliance standards.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales