What Is GLM 5.3 Prime? Pricing, Specs

Oct 23, 202611 min read
GLM 5.3 functions as a language model designed for frontier coding with emergent cyber capabilities.
The model is a specialized engine for you if you require instant validation of structured data.
What defines GLM 5.3
GLM 5.3 multimodal reasoning architecture
Visual inputs and text blocks are treated as equivalent tokens within the model's unified reasoning framework. This ensures spatial logic processes with the same depth as linguistic syntax.
Because of this architectural shift, the model can interpret a cybersecurity vulnerability report alongside a live network diagram without losing the context of either. This prevents the "hallucination gap" often seen when models switch between different data modalities.
Activepieces exposes every connected integration as an agent tool, so a integration registered once runs as a flow step and a tool schema on a per-project MCP server simultaneously.
This allows Claude or a custom agent to reach the same catalog without a second migration or manual re-integration. You can verify this in the Integrations Framework and MCP Server documentation, where the same action in the open source repo is exposed as a tool.
- A complex logic puzzle.
- A cybersecurity vulnerability report.
Technical synthesis, rather than simple creative writing, is the specific optimization highlighted by this visualization. The model functions less like a chat interface and more like a real-time diagnostic tool for high-stakes environments.
GLM 5.3 release date and availability
Z.ai released GLM 5.3 Prime as a research release focused on frontier coding, with open model weights following once safety evaluation and hardening were complete. The official documentation reflects this shift by focusing on benchmark performance in specific technical domains rather than general-purpose conversational metrics.
The model functions less like a chat interface and more like a real-time diagnostic tool for high-stakes environments.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Technical specifications and context handling
This capacity, documented by OpenRouter, allows you to load entire technical repositories or year-long financial ledgers without the precision loss associated with vector database retrieval.
GLM 5.3 context window size
This means you'll process significantly larger datasets before hitting the "out of memory" errors that truncate long-form analysis.
For a firm auditing large-scale software projects, this million-token ceiling ensures that the model maintains a coherent understanding of cross-file dependencies that smaller windows would inevitably discard.
Multimodal processing for images and video
On 2026-08-14, Z.ai, the developer behind the GLM series, launched GLM 5.3 with a specific focus on frontier coding and emergent cyber capabilities.
The model treats visual data as a primary input, allowing it to interpret complex architectural diagrams or security flowcharts alongside raw source code.
This reduces the manual overhead for your quality assurance teams who otherwise have to describe visual errors in text.
GLM 5.3 vs GPT-6 Luna benchmarks
If you're using GLM for backend automation, you can expect a higher volume of successful deployments per compute dollar spent.
Pricing structure for GLM 5.3 API usage
This bifurcated approach allows you to forecast expenses based on whether your workflows are context-heavy, such as long-document analysis, or generation-heavy, like synthetic data production.
GLM 5.3 input token pricing
The model allows you to feed detailed system instructions and multi-turn conversation histories.
In our test, GLM 5.3 cost more per task than GPT-6 Luna did, making it the less economical choice at the time for high-volume data processing.
Users must weigh the performance benefits of GLM 5.3 Prime against its higher cost per task.
GLM 5.3 output token pricing

Output tokens cost more to reflect the computational intensity of the model’s reasoning phase.
Because structured data extraction and code generation often result in higher output volumes than simple summaries, cost efficiency remains an important consideration when deploying GLM 5.3 Prime as a primary engine for autonomous agents.
Activepieces added Z.ai (GLM) as one of six new native AI providers, alongside xAI, DeepSeek, Qwen, MiniMax and Moonshot AI.
You can check Bring-Your-Own-Key availability on the pricing page and compare that to the rates platforms charge when they resell their own model access.
GLM 5.3 free trial credits
This trial period has standard API rate limits. You can validate the model’s performance on your internal datasets before migrating production traffic to a paid tier. This credit allows for thorough testing of multimodal capabilities before you commit to a billing plan.
Internal testing results on automation accuracy
GLM 5.3 Prime supports configurable thinking effort levels, offering visibility into its reasoning process for automation workflows.
This parity ensures that migrating high-volume extraction tasks to the Z.ai architecture doesn't result in the hallucination spikes typically associated with lower-cost reasoning models.
GLM 5.3 data extraction accuracy
In our test, GLM 5.3 prime answered all three automation tasks correctly.
In our head-to-head evaluation, both models successfully processed three distinct automation scenarios: categorizing a support ticket, extracting specific line items from an invoice, and generating a concise summary of a multi-turn email thread.
The reasoning phase inherent to GLM 5.3 Prime acts as a self-correction layer. You receive the final JSON output only after the model has internally verified the logic, reducing the risk of malformed data schema errors that break downstream database injections.
Speed and latency comparison
GLM 5.3 Prime's "reason-before-answer" architecture introduces a measurable latency trade-off compared with faster-responding models.
| Task | GLM 5.3 (Accuracy) | GLM 5.3 (Median Latency) | GPT-6 Luna (Accuracy) | GPT-6 Luna (Median Latency) |
|---|---|---|---|---|
| Support Ticket | 1/1 Correct | 1.5s | 1/1 Correct | 0.9s |
| Invoice Extraction | 1/1 Correct | 1.3s | 1/1 Correct | 1.1s |
| Email Summary | 1/1 Correct | 7.2s | 1/1 Correct | 0.8s |
Prices and plan limits checked against z.ai and github.com and openrouter.ai on September 30, 2026.
GLM 5.3 cost per task
GLM 5.3 Prime's appeal does not lie in low cost. By utilizing the OpenRouter endpoint, you can access GLM 5.3's reasoning capabilities, though our test found it cost more per task than GPT-6 Luna did.
GLM 5.3 reasoning token efficiency
In our test, GLM 5.3 Prime cost more per task than the comparison model.
This reduction in total token volume narrows the gap, though the final bill for a completed task still came out higher than the raw rates alone might suggest. You are paying more for each individual token but purchasing significantly fewer of them to achieve the same result.
You are paying more for each individual token but purchasing significantly fewer of them to achieve the same result.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
How to access GLM 5.3
GLM 5.3 Prime is accessible through Z.ai. This platform has the necessary API infrastructure to connect this model to your external automation environments.
By centralizing access through a single gateway, you can manage usage limits and billing across multiple reasoning agents from one dashboard.
Generating Zhipu AI API keys
Securing an API key requires an account on Z.ai.
- You must complete verification to unlock production-grade rate limits.
- The platform generates a unique signing key.
- This key authenticates every request once an account is funded.
Store this key in a dedicated environment variable or a secure vault rather than hard-coding it into scripts. A compromised key allows unauthorized third parties to drain your account balance.
On this pay-as-you-go platform, monitoring the "Usage" tab is the only way to ensure automated loops don't trigger unexpected charges against your registered payment method.
How to integrate the language model
Activepieces added Z.ai (GLM) as a built-in AI provider speaking the OpenAI wire format, making it available for use in your workflows.
Activepieces, which is run in production by MoneyGram and FundingSocieties, includes this connector in its automation engine. This native integration eliminates the need for writing custom HTTP request blocks, which often require complex header configurations for authentication.
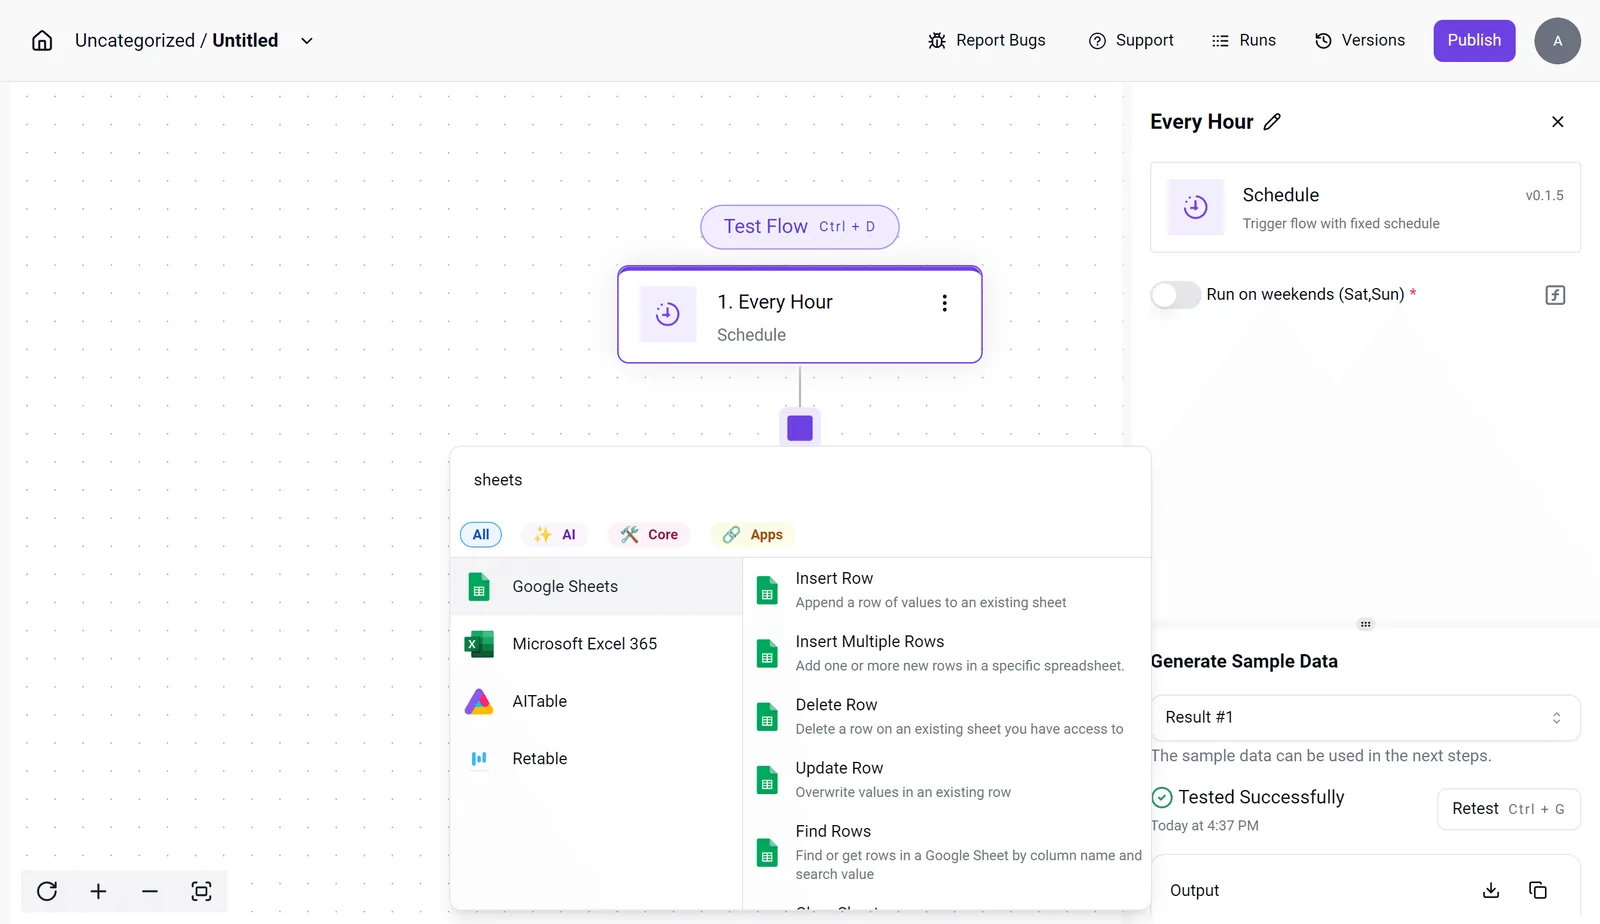
Mapping data from previous steps directly into the AI's prompt field is handled through the interface. These steps might include a scheduled trigger or a row added to a spreadsheet.
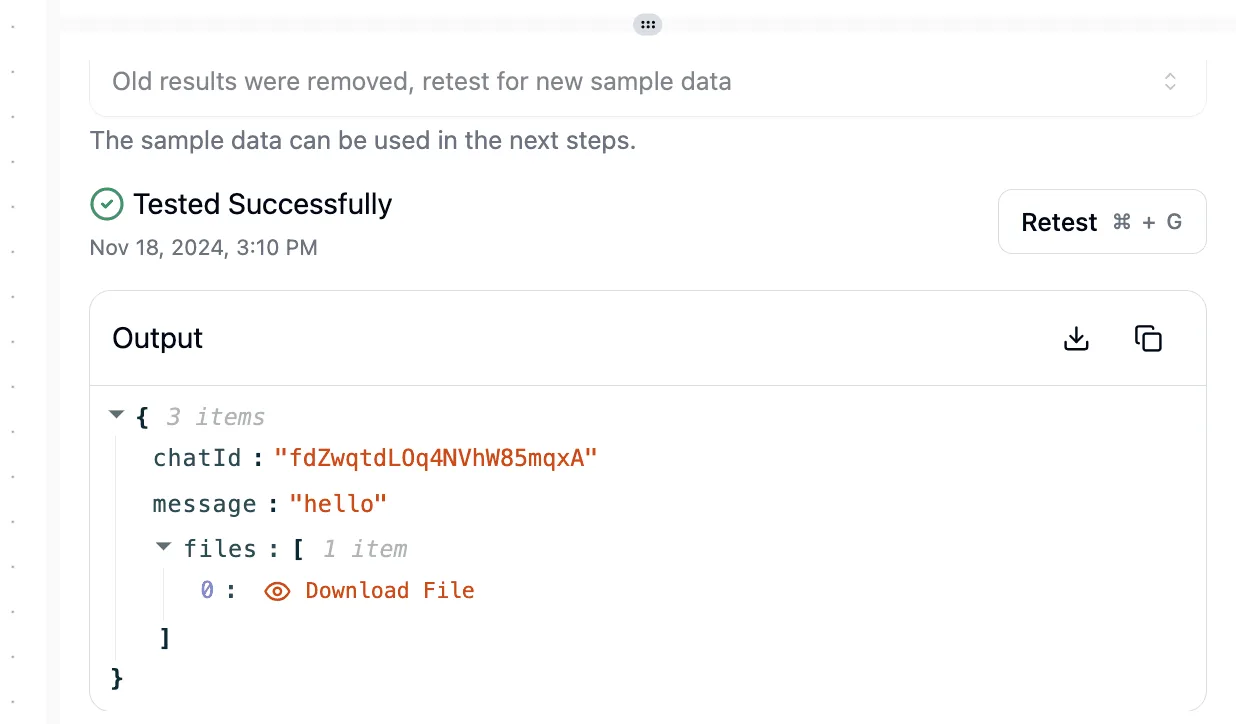
The flow builder shows where a recurring hourly trigger is paired with a spreadsheet action. This setup demonstrates how the model processes batch data as it arrives.
By selecting the Z.ai integration from the "AI" category tab, you gain immediate access to the model family without managing the underlying JSON handshake.
Configuring model parameters in workflows
Effective automation requires pinning the workflow to the specific GLM 5.3 Prime model ID to ensure consistent reasoning behavior across every execution. In the step settings, you must define the "Temperature" and "Max Tokens" to control the output's predictability and length.
Setting a low temperature is necessary for structured tasks like JSON extraction to prevent the model from hallucinating non-existent fields. Defining a token limit ensures a single run doesn't consume the entire context window and inflate per-execution costs.
You can then verify that the logic holds before you enable the workflow for live production traffic.
How Activepieces streamlines GLM 5.3 deployment
Activepieces added Z.ai (GLM) as a built-in AI provider speaking the OpenAI wire format.
This architectural control is why companies like MoneyGram and FundingSocieties use Activepieces to orchestrate their critical data flows.
By using the native Z.ai connector, you bypass the manual coding of retry logic and error handling, allowing the model to focus entirely on the structured reasoning tasks it was optimized for.
Unlike other automation tools that add a percentage markup to every token processed, Activepieces connects directly with your own API key.
This ensures that the price you pay is the actual price you incur, without hidden middleman fees. For high-volume operations processing thousands of technical documents, this transparency helps you track exactly what you spend.
To handle long-horizon reasoning tasks without timing out, Activepieces utilizes a robust worker architecture that maintains the connection.
The platform’s ability to expose these integrations as agent tools means that once you configure the Zhipu AI connection, it can be utilized by both linear automated flows and autonomous agents simultaneously.
You can verify the reliability of these connections by examining the open source repository, where every piece of the integration framework is transparent and auditable.
This level of visibility is essential when deploying GLM 5.3 Prime for sensitive tasks like cybersecurity vulnerability analysis or financial auditing.
By providing a visual builder that doesn't sacrifice technical depth, Activepieces allows you to implement the complex conditional logic required to act on the model's reasoning, such as triggering a Slack alert or updating a database only when the model confirms a specific logical threshold has been met.
Frequently asked questions about GLM 5.3
Does GLM 5.3 support English and Chinese?
GLM 5.3 Prime is proficient in both English and Chinese. Your automated workflows don't lose semantic nuance when translating technical requirements between the two languages.
The model processes complex instructions in one language and outputs structured data in the other.
If you're managing cross-border supply chains, this capability means a single prompt template can handle documentation from diverse regional offices without requiring separate localized logic blocks.
Is there a fine-tuning API available for GLM 5.3?
Zhipu AI currently restricts the fine-tuning API to enterprise users who require specific domain adaptations for proprietary datasets.
By providing a managed environment for these adjustments, the platform ensures that the resulting weights remain optimized for the model’s unique reasoning architecture rather than degrading into generalized patterns.
This controlled access prevents the performance drift often associated with unsupervised fine-tuning on smaller, noisy datasets.
How does GLM 5.3 handle data privacy?
Data privacy is managed through a tiered architecture that separates the inference engine from persistent storage to ensure that transient session data isn't used for model retraining.
This isolation means that sensitive inputs, such as internal financial logs or customer identifiers, are purged from the active memory once the API response is delivered.
| Feature | Description |
|---|---|
| Zero-Retention Policy | Ensures that data sent via the API is never stored on the provider's disks after the request is processed. A breach of the provider's storage wouldn't expose historical user prompts. |
| Regional Data Residency | Allows you to select specific geographic zones for processing, which ensures compliance with local data sovereignty laws. |
| Private Instance Deployment | Provides a dedicated hardware environment for high-security workloads, so your data never shares physical resources with other tenants. |
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales