Mistral Large 4: A Guide to the New Frontier Model

Nov 10, 202611 min read
The emergence of frontier models has fundamentally altered the landscape of digital workflows, enabling systems to process complex reasoning tasks that were previously impossible.
As developers integrate these capabilities into their stacks, often utilizing platforms like Activepieces to orchestrate their logic, the focus shifts from simple task execution to autonomous decision-making. This evolution requires a new understanding of how large language models interact with external tools and APIs.

By leveraging advanced prompting techniques and structured output, organizations can build resilient agents that adapt to changing data environments in real time. Understanding these underlying mechanics is essential for anyone looking to master the next generation of intelligent automation.
How to use Mistral Large 4
Released in public preview on October 6, 2026, Mistral Large 4 is a general-purpose multimodal model, with open weights due at the end of October, designed to handle high-reasoning tasks without the proprietary lock-in of closed-source competitors. It utilizes a granular Mixture-of-Experts (MoE) architecture to activate only the necessary parameters for a specific prompt.
What open-weight means for Mistral Large 4
An open-weight model provides a middle ground between fully closed-source systems and traditional open-source software. While a closed-source model like GPT-6 Astra is a "black box" accessible only via a vendor's API, an open-weight model makes its learned parameters (the "weights") publicly available for download.
Once the weights are released, an organization will be able to host the model on its own private servers, ensuring complete data residency and eliminating reliance on a third-party provider's uptime.
However, being open-weight does not mean the model is free of licensing or that it lacks a managed version. Users can still access Mistral Large 4 through managed APIs like La Plateforme for convenience, paying per token just as they would with a closed model.
The "open" nature refers to the portability of the intelligence; you have the right to take the model's brain and run it on your own hardware if the managed service no longer meets your needs.
This MoE mechanism functions by breaking the massive neural network into several specialized sub-networks, or "experts," each trained to handle different types of data or logic.
Instead of forcing every request through the entire model, a gating layer acts as a router, sending the prompt only to the most relevant experts.
By activating just a fraction of the total model per request, the system achieves the intelligence of a massive model while using far fewer active parameters.
However, this architecture can introduce noticeable latency for complex logical deductions compared to smaller, faster models. This choice makes it a direct peer to flagship offerings like Claude Fable 5.1 from Anthropic, which targets similar long-horizon agentic work.
The model represents a shift in how enterprises value intelligence versus autonomy. The following diagram illustrates the internal logic of the system:
While the multimodal inputs let the model process visual and textual data simultaneously, specialized routing is made possible by the Mixture-of-Experts branching.
This means a developer can feed a schematic directly into the model to generate a bill of materials, rather than relying on a separate OCR layer.
Reselling you a model is deciding your AI strategy for you. Activepieces offers a Mistral AI piece with actions covering chat completion, code completion, audio transcription, speech generation, moderation, model info, file management, and beta agents.
Reselling you a model is deciding your AI strategy for you.
This transparency allows teams to verify Bring-Your-Own-Key availability across different tiers, keeping the financial strategy in your hands rather than letting a platform sell your own compute back to you.
Mistral Large 4 excels where the nuance of the instruction determines the success of the entire workflow, even though Claude Haiku 5.5 is often better for high-volume classification to minimize costs.
This takes minutes, not a project: automate it in Activepieces free.
Why Mistral Large 4 changes automation
By consolidating high-reasoning logic and tool execution into a single, open-weight architecture, Mistral Large 4 simplifies complex automation workflows.
While models like Claude Haiku 5.5 handle the cheap, high-volume routing, Mistral Large 4 is built to manage the structural integrity of the entire workflow.
Instead of relying on fragile, multi-model handoffs that often break when a proprietary provider updates an API, developers can now move toward a unified stack. The following capabilities define its utility in enterprise environments:
- Native Function Calling allows the model to interact directly with external APIs. This allows the LLM to trigger actions in a database or CRM rather than just describing them.
- Multi-step Reasoning handles complex logic chains. A single prompt can decompose a high-level goal into a sequence of verified sub-tasks.
- The model maintains the specific business context required for accurate execution.

By utilizing a model with these specific strengths, an organization avoids the complexity tax of building custom glue code to manage short context windows or unreliable tool outputs.
These pillars ensure that the model acts as a reliable controller for software agents. The result is a more resilient automation stack that remains functional even as the scale of data increases.
Measurable performance gains in reasoning and multilingual tasks
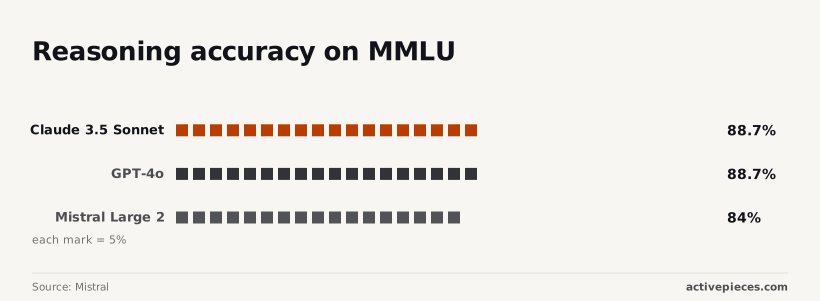
Mistral Large 4 performs strongly on coding benchmarks; the 2024 figures below, from Mistral AI, were measured on older models such as Claude 3.5 Sonnet and GPT-4o.
The model’s architecture as an open-weight hybrid instruct-and-reasoning Mixture of Experts (MoE) supports these gains. Mistral notes this unifies agentic capabilities to reduce the need for separate fine-tuned models in finance or cybersecurity workflows.
The following 2024 data illustrates how Mistral Large 2 closed the gap with GPT-4o and Claude 3.5 Sonnet on general reasoning:
- Claude 3.5 Sonnet: 88.7%
- GPT-4o: 88.7%
- Mistral Large 2: 84.0%
Mistral Large 2 scored 84.0% on MMLU, which trailed the 88.7% shared by GPT-4o and Claude 3.5 Sonnet; those older figures say nothing about how Mistral Large 4 compares.
Multi-step logic chains remain reliable even when processed outside of the dominant American ecosystems because of this convergence in reasoning scores. Consequently, the decision to use a specific provider now rests on infrastructure costs rather than a deficit in model capability.
You can follow the rest of this with the builder open. Start free, no card.
Connecting Mistral Large 4 to your Activepieces workflows today
Every integration in Activepieces is available as an MCP tool on its per-project MCP server, reachable from Claude, ChatGPT, Cursor, or any agent you built yourself.
Registering an integration once allows it to run as a step in a flow or as a tool for an agent, ensuring that Activepieces' integration catalog does not require a second migration to be useful to your models.
By using the Mistral AI piece, updated on September 24, 2026, users can add chat completion steps to their workflows without rewriting the surrounding data transformation steps.
This modularity ensures you swap the model integration rather than rebuilding the entire workflow when a provider changes their pricing structure. The following steps enable the flagship Mistral model within your automation canvas:
- Locate the Mistral AI integration in the step selector and choose the "Chat Completion" action.
- Input your API key from the Mistral La Plateforme console to authenticate the connection.
- Configure the "System Message" to define the agent’s persona and the "User Message" to map data from previous steps.
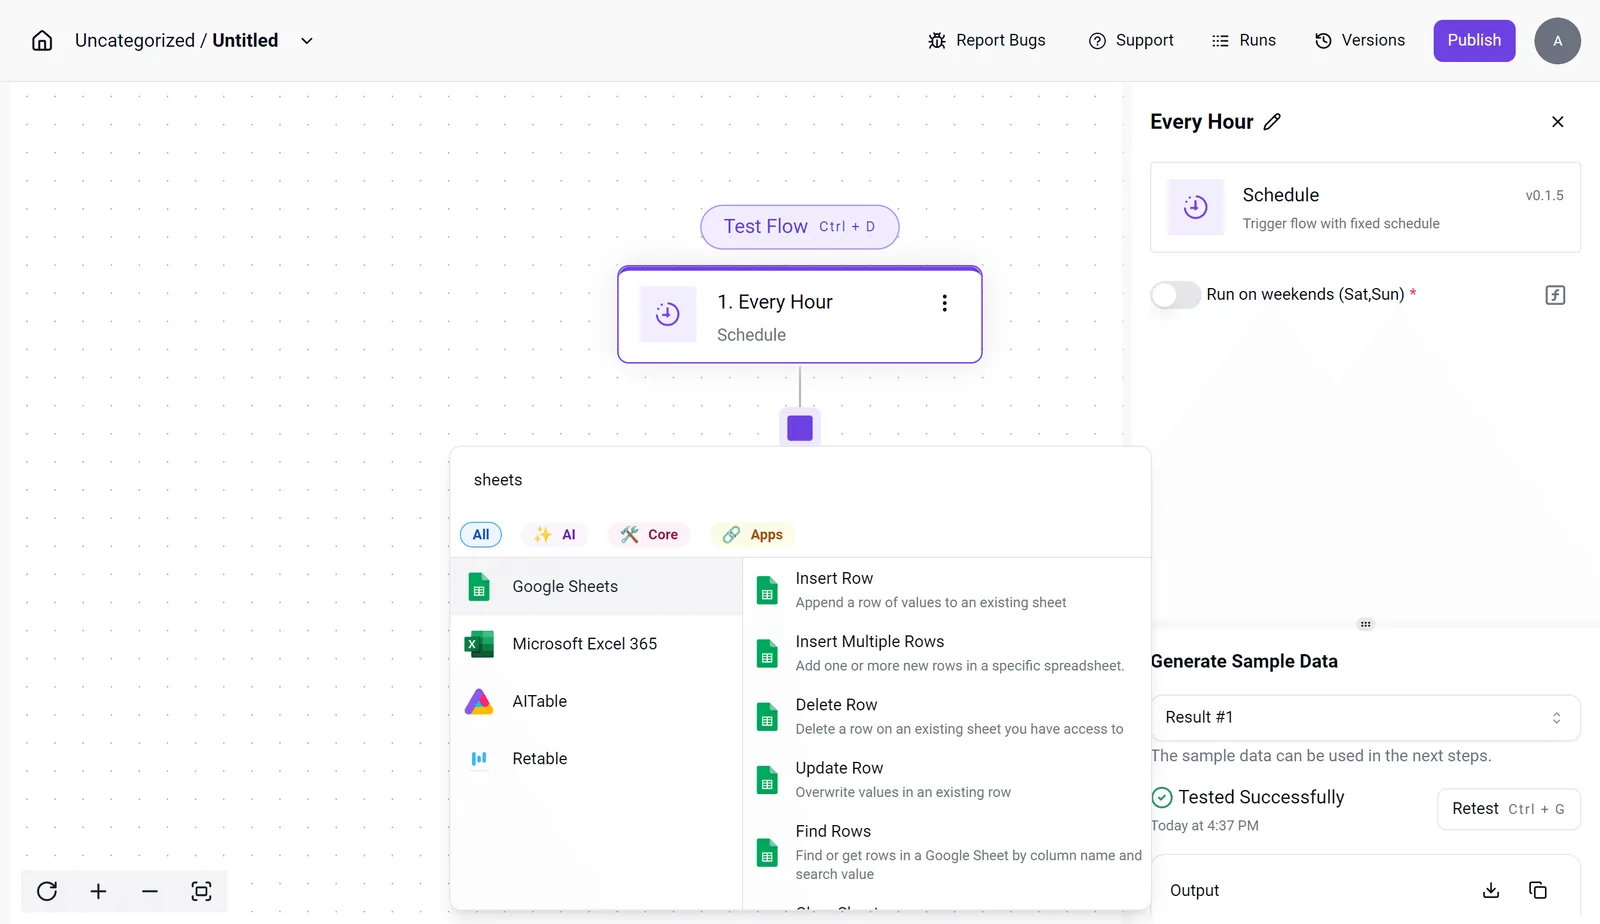
The interface has granular control over the execution environment, as seen in the workflow builder below.
Displayed in the Activepieces flow builder is a scheduled trigger paired with spreadsheet actions. This shows how a user can insert a model between data retrieval and final storage.
By keeping logic visible to non-technical stakeholders, you prevent the "black box" effect of custom scripts. Once the flow is active, the engine handles retries and logging automatically. A temporary API timeout does not result in permanent data loss.
Internal test results on three common automation tasks
Mistral Large 4 matches GPT-6 Luna's accuracy across these tasks but carries a significant latency penalty that impacts real-time user experiences.
Our internal testing on 2026-10-09 utilized OpenRouter to evaluate these models across three core operational workflows. Mistral’s native reasoning phase comes at the cost of execution speed.
| Task | Model | Accuracy | Median Latency |
|---|---|---|---|
| Ticket Sorting | Mistral Large 4 | Correct | Higher |
| Ticket Sorting | GPT-6 Luna | Correct | Lower |
| Invoice Extraction | Mistral Large 4 | Correct | — |
| Invoice Extraction | GPT-6 Luna | Correct | Lower |
| Email Summarization | Mistral Large 4 | Correct | — |
| Email Summarization | GPT-6 Luna | Correct | Lower |
Prices and plan limits checked against docs.mistral.ai and mistral.ai and github.com and openrouter.ai and docs.claude.com and openai.com and gemini.google on October 9, 2026.
GPT-6 Luna is the superior choice for high-volume, latency-sensitive tasks. Mistral Large 4 also sorted support tickets correctly in our test, though it took longer to do so.
The trade-off is measurable. Mistral’s internal reasoning step eliminates the "hallucinated fields" common in smaller models, yet it requires a more patient infrastructure to handle the extended time-to-first-token.
To save a few milliseconds at the cost of data integrity is to choose the wrong model. Reliability at this level of complexity changes the math for long-term maintenance.
How to compare model costs
It provides a significant margin for error in complex agentic workflows.
The delta between providers determines whether a prototype remains a cost-center or becomes a viable production tool when an enterprise processes millions of tokens daily. The following table compares Mistral Large 4 with earlier-generation GPT-4o and Claude 3.5 Sonnet list prices for input and output costs per million tokens:
| Model | Input Cost (USD) | Output Cost (USD) |
|---|---|---|
| Mistral Large 4 | $0.70 | $2.10 |
| Claude 3.5 Sonnet | $3.00 | $15.00 |
Significantly more sustainable on Mistral’s infrastructure are output-heavy tasks, such as generating long-form documentation or complex codebases. This is the primary takeaway for a budget-conscious architect.
This allows for more aggressive iterative testing without hitting monthly budget caps.
However, the engineering team only realizes these savings if they avoid the proprietary lock-in of specific provider ecosystems.
If a company uses a specialized markup language unique to one platform, technical debt accrued during migration may outweigh the immediate per-token discount. Efficiency is found in the balance between raw compute price and the portability of the underlying logic.
Why watch future model deployments
By transitioning from centralized API access to fully independent, self-hosted environments, the roadmap for Mistral Large 4 prioritizes sovereign data control. This shift ensures that European enterprises can move away from shared infrastructure where data residency is a legal liability.
The focus shifts from general capability to the specific industrial requirements of the Eurozone as the model moves through its rollout phases.
The Mistral Deployment Roadmap includes Public Preview access via API and the open-weight release for self-hosting. Fine-tuning availability for specialized domains and regional expansion follow.
Before teams commit the heavy capital required for private hardware, logic can be validated on hosted endpoints. Once Mistral releases the weights, the operational cost moves from a per-token variable expense to a fixed infrastructure cost, which stabilizes the balance sheet for high-volume automation.
The subsequent availability of fine-tuning is the critical step for sectors like finance and manufacturing.
It allows the model to ingest proprietary terminology that general-purpose weights often hallucinate.
Frequently asked questions
Which frontier models are viable for production environments is often dictated by token limits and data residency requirements.
Mistral Large 4 is an open-weight flagship for European data sovereignty, with weights due to be released at the end of October 2026., but its utility is restricted if the underlying infrastructure lacks the specific regions required for local compliance.
While Mistral Large 4 is available through the hosted preview API, with open weights due at the end of October, and focuses on multimodal reasoning, Claude Opus 5.5 and GPT-6 Astra remain managed APIs for long-horizon agents and complex coding respectively.
Data privacy remains a function of the provider’s specific service level agreement rather than the model name itself.
A standard API call often permits metadata logging for service improvements, so an enterprise must negotiate a zero-retention policy to prevent proprietary prompts from being stored on vendor hardware.
Currently, model availability is fragmented across several specialized ecosystems:
- The Google Vertex AI platform, which provides access to the Gemini 3.8 Flash series for long-horizon engineering.
- The Anthropic Console, which serves the Claude Fable 5.1 model for demanding reasoning tasks.
- The Azure OpenAI Service, which hosts the GPT-6 suite for organizations requiring Microsoft-aligned security wrappers.
Choosing a provider based solely on a single benchmark score results in technical debt. The cost of migrating integrated prompts between different markup formats often exceeds the initial savings of a cheaper token price.
Related reading
References
Build it
Set this up in minutes.
No code required. Connect your accounts, and Activepieces runs it from there.
Start free Talk to sales