Xing4.0-29B-A4B (2026): 29B MoE Model With Only 4B Active
Nov 1, 20268 min read
Xing4.0-29B-A4B is a high-efficiency large language model designed for agentic workflows, utilizing a mixture-of-experts architecture while maintaining the computational footprint of a 4B active-parameter model.
Xing4.0-29b-a4b launches as a lightweight agentic model
Xing4.0-29B-A4B has 29 billion total parameters. This sizing keeps monthly hosting bills predictable for finance managers.
This takes minutes, not a project: automate it in Activepieces free.
Architecture: 29B total vs 4B active parameters
By utilizing a Mixture-of-Experts (MoE) architecture, Xing4.0-29B-A4B delivers high-reasoning performance while only engaging a small fraction of its total parameter count for any specific task.
This design allows the model to store a 29-billion parameter knowledge base while activating only a fraction of those parameters for any given task.
How MoE reduces active parameters in xing4.0-29b-a4b
To prevent the system from processing irrelevant data, the MoE framework replaces traditional dense layers with specialized expert blocks. In the Xing4.0-29B-A4B architecture, a router directs each incoming token to only 4 specific expert blocks out of the total pool.
According to Huggingface, this mechanism limits the active parameter count to just 4 billion per token. An enterprise's inference workload corresponds to the compute footprint of a 4B parameter model.
As Hugging Face illustrates, a single input token enters a router, which activates only 4 specific 'expert' blocks per token (about 4B active parameters) out of the total 29B parameter pool.
An enterprise's inference workload corresponds to the compute footprint of a 4B parameter model.
By isolating these experts, the model activates only a subset of its parameters for each token.
Comparing xing4.0 to mixtral and deepseek architectures
As a next-generation model in the series formerly known as TeleChat, Xing4.0 provides a more aggressive efficiency ratio than its predecessors or larger competitors.
While it maintains a total of 29 billion parameters, only 4 billion of those are active per token.
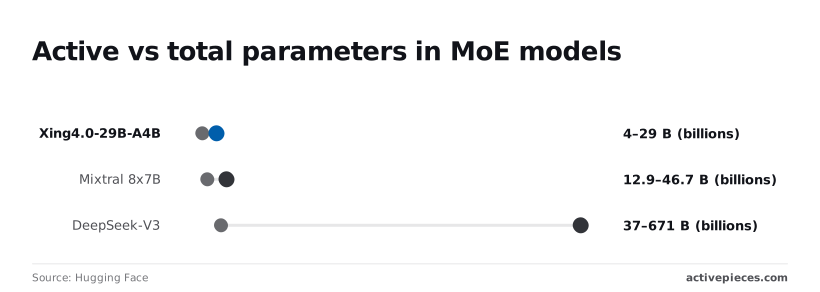
| Model | Active Parameters | Total Parameters |
|---|---|---|
| Xing4.0-29B-A4B | 4 billion | 29 billion |
| Mixtral 8x7B | 12.9 billion | 46.7 billion |
| DeepSeek-V3 | 37 billion | 671 billion |
Prices and plan limits checked against huggingface.co and huggingface.co on September 29, 2026.
For a finance operations team, these figures translate directly to the bottom line.
Xing4.0 delivers a 29B parameter knowledge depth while activating only 4B parameters per token.
Connecting xing4.0-29b-a4b to your Activepieces workflows
Once a connector is registered in this MIT-licensed platform, it is simultaneously available as a flow step and as a tool schema on a per-project MCP server, reachable by any agent you build.
This removes the need for a second migration or manual schema exports, as the same integration code in the packages/pieces directory of the open-source repo powers both deterministic flows and agentic tool calls.
By utilizing this model within an automated framework, you move from static chat interfaces to dynamic agents that can independently update ledgers or trigger procurement cycles.
Step 1: Obtain your API endpoint and key
Before the automation platform can securely route requests to the model, you must obtain a valid authentication token and the specific URL for your inference provider.
Access your provider’s dashboard to generate a secret key, which acts as the digital handshake between the workflow and the GPU cluster. Ending typically in /v1, the Base URL ensures the traffic is directed to the correct API version rather than a legacy port.
Step 2: Use the OpenAI-compatible provider block
This compatibility allows you to skip manual JSON coding for basic prompts.
- Add the OpenAI integration to your workflow canvas.
- Select the "Ask Assistant" or "Chat" action to define the model's role.
- Type
xing4.0-29b-a4bmanually into the model field so the provider knows exactly which weights to load for your task.
Step 3: Configure the HTTP request for custom tools
To handle complex agentic workflows where the model must call external functions, you must use the HTTP Request integration to define precise JSON payloads. This step is necessary because high-volume tool use requires specific headers that standard blocks might strip away.
Set the method to POST to send data to the model. Append /chat/completions to your Base URL to reach the endpoint for dialogue and tool calls.
Include Authorization: Bearer [Your_Key] and Content-Type: application/json in the headers. Define your tools array in the body, outlining the specific SQL queries or API calls the model is permitted to execute.
You can follow the rest of this with the builder open. Start free, no card.
Performance in complex reasoning and tool use
By utilizing a Mixture-of-Experts architecture that activates only 4B parameters per token, Xing4.0-29B-A4B delivers efficient reasoning.
Xing4.0-29b-a4b vs Gemini 3.8 Flash tool-call accuracy
Whether an automated workflow successfully triggers an external API or fails due to a malformed JSON object is determined by precision in syntax generation.
Because a single misplaced bracket in a database query can halt a production pipeline, necessitating manual intervention from a DevOps engineer, this reliability is critical.
In tests involving the Snowflake data platform, the model consistently maps natural language requests to the correct SQL parameters. Automated reports pull the exact datasets requested by the finance team.
Why reasoning density matters for agents
To maintain its internal state across multiple turns without losing the original objective, an agent relies on high reasoning density. This is a requirement for any task that involves more than a single API call.
If a model lacks this density, it often hallucinations parameters or forgets previous constraints, which leads to redundant API calls and wasted compute costs.
Before deciding on the next step, the model must evaluate the output of one tool. This logical coherence means the thought process must remain stable even as the context window fills with raw data logs.
When an agent is told to update a record in the Salesforce customer relationship management platform only if the last contact was more than thirty days ago, the model must satisfy that constraint.
It must hold that temporal logic in its active weights while simultaneously formatting the update command.
If a tool returns a 403 Forbidden error, a high-density model can autonomously pivot to an alternative authentication path for error recovery rather than simply repeating the failed request and depleting the API credit balance.
By concentrating its intelligence into a smaller active footprint, the model navigates these technical hurdles for minor transactional updates.
Frequently asked questions about xing4.0-29b-a4b
Can i run xing4.0-29b-a4b on local hardware?
Because its 4-bit quantized weights fit within about 15GB of VRAM, within the memory limits of a single consumer graphics card, you can deploy this model on local consumer hardware.
This local deployment capability means a firm can process sensitive financial data without sending packets over the public internet, satisfying internal data residency requirements.
Unlike massive flagship models that necessitate a multi-node cluster, this model functions on a single workstation. A small DevOps team can maintain the stack without specialized infrastructure engineers.
Is xing4.0-29b-a4b compatible with the OpenAI API?
By supporting the standard OpenAI-compatible chat completions schema, the model allows teams to swap it into existing agentic pipelines without rewriting their core integration logic. Because it adheres to this common interface, developers can use popular orchestration libraries to manage the model.
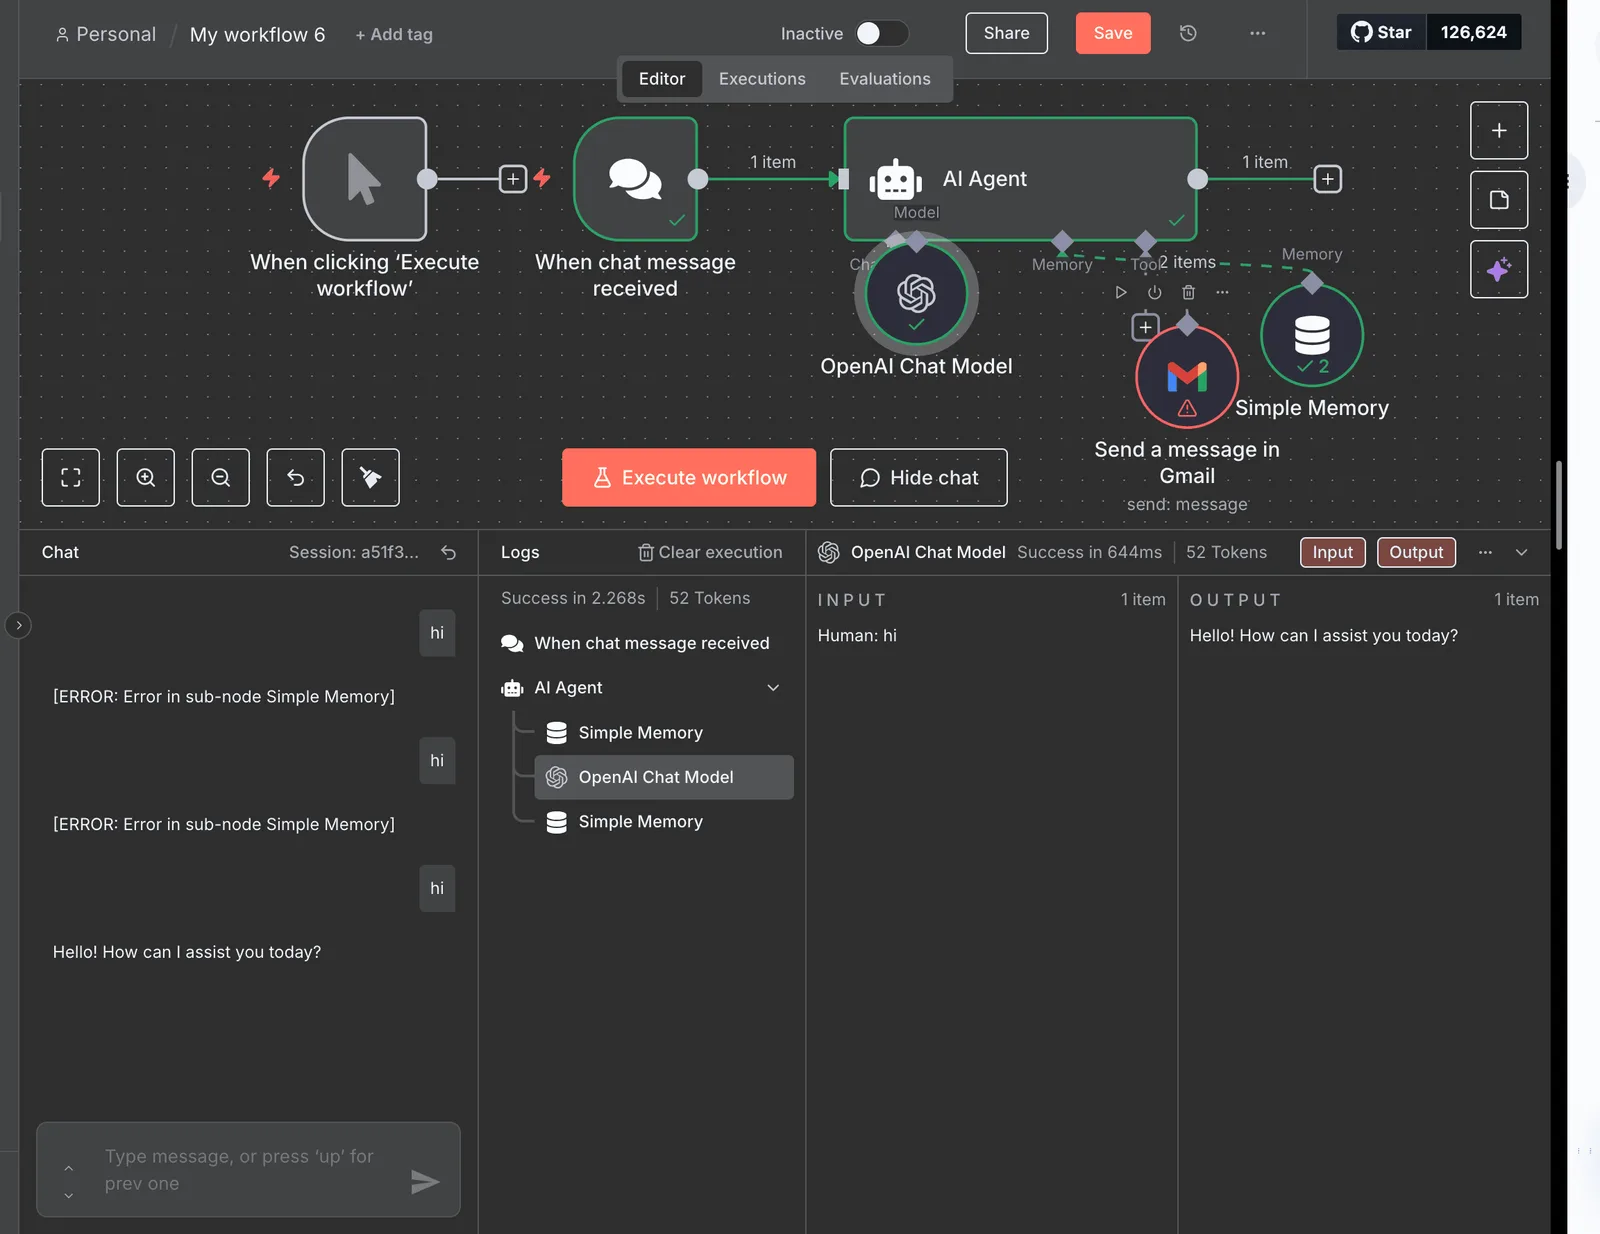
To transition from a proprietary service to this self-hosted alternative, you only need to change the base URL and API key. This compatibility ensures that existing prompt templates and system instructions remain functional.
Does this model support multi-turn tool calling?
To execute a sequence of functions and refine its next step based on the output of the previous action, this model natively supports multi-turn tool calling.
This capability is essential for workflows that require a loop of feedback, such as querying a database, receiving an error, and then correcting the SQL syntax automatically.
By handling these iterative cycles, the model can complete complex tasks without human intervention. It can query a customer database to retrieve a unique identifier.
It can use that identifier to pull transaction history from a separate billing system. It can cross-reference those transactions against a shipping log to identify a specific delay.
This logical chaining ensures that the agent reaches a final resolution rather than stopping after the first API response.
Related reading
References
Build it
Set this up in minutes.
No code required. Connect your accounts, and Activepieces runs it from there.
Start free Talk to sales