What Is Xing4.0 29B Model? A Versatile Agentic LLM
Nov 9, 202610 min read
The Xing4.0 29B model represents a significant leap in open-source large language models, offering a unique balance between parameter efficiency and high-level reasoning capabilities, as covered in this Xing4.0 29B A4B agentic MoE model guide.
As developers integrate these weights into local environments or cloud clusters, many are leveraging Activepieces to automate the surrounding data pipelines, ensuring that the model receives clean, real-time context for its inference tasks.
By utilizing a Mixture-of-Experts architecture, Xing4.0 keeps per-token compute low while delivering high-level reasoning capabilities.
Understanding its quantization requirements and hardware compatibility is essential for anyone looking to deploy this architecture for production-grade applications in the current year.
Xing4.0 29B is a sparse large language model architecture that utilizes an A4B mechanism to deliver high-level reasoning capabilities while maintaining the low operational overhead of a significantly smaller parameter set.
What is the Xing4.0 29B A4B model?
Xing4.0 29B mixture-of-experts efficiency
When a model needs to deliver frontier-class reasoning at a fraction of the compute cost, developers often turn to sparse Mixture-of-Experts (MoE) architectures.
Huggingface reports that China Telecom Artificial Intelligence Technology Co., Ltd. designed the Xing4.0 29B A4B model specifically for this purpose. By isolating computational paths, the architecture decouples a model's total capacity from its per-token execution cost.
To evaluate this efficiency, look at the mathematical relationship between total parameters and active parameters per token. According to Hugging Face repository documentation, Xing4.0 29B routes data through 4 billion active parameters out of a 29 billion total parameter pool.
By isolating computational paths, the architecture decouples a model's total capacity from its per-token execution cost.
Hardware and hosting costs for Xing4.0 29B
Nobody notices the scale of the system until the bill arrives, but with MoE, you only pay the compute cost of a small model per token, while the hardware must still hold the full 29B weights.
Arxiv notes that legacy MoE models like Mixtral 8x7B require 13 billion active parameters out of 47 billion total parameters to process a token. That increases the baseline hardware requirement to multiple enterprise GPUs.
37 billion active parameters out of 671 billion total parameters is the requirement for DeepSeek-V3, according to Theterminal’s analysis. That mandates massive cluster orchestration that's out of reach for mid-market infrastructure budgets.
Xing4.0 29B routed and shared experts
Internally, the model structures its workload through two distinct types of specialized networks. Benchmarks published by MindStudio show the architecture relies on 64 routed experts.
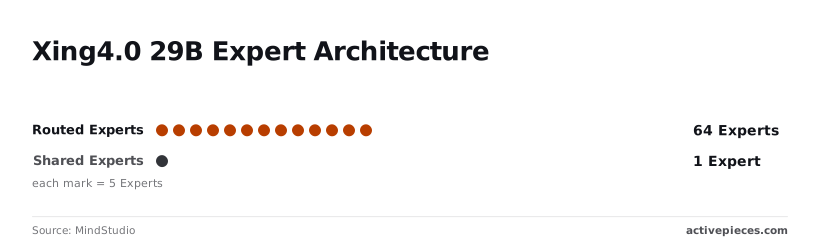
Dedicated neural pathways process specific domain tasks instead of generalized layers. MindStudio indicates that 1 shared expert stabilizes this routing.
It captures universal linguistic patterns across all tokens so that specialized experts don't lose contextual coherence during complex reasoning chains.
Xing4.0 29B context window for enterprise data
Because of this structural efficiency, you can handle massive enterprise datasets without dropping information.
Architectural sparsity allows for massive data ingestion boundaries. 256,000 tokens is the threshold that allows your operations team to feed entire codebase repositories or multi-year financial ledgers directly into a single prompt without chunking data.
Architectural sparsity allows for massive data ingestion boundaries.
Activepieces ensures every connector is an agent tool by exposing its 735 integrations through a per-project MCP server, which means developers can instantly equip their AI agents with a vast library of external capabilities.
This unified catalog removes the need to re-integrate systems for agents, as the same logic in the open source repo handles both automation and model tool-calls.
Everything below works on Activepieces' free plan. Start without code or a credit card.
A4B architecture for 29 billion parameters
The model utilizes a Mixture of Experts architecture. It contains 29B total parameters, meaning the system holds a deep knowledge base while maintaining efficiency.
Accessing Xing4.0 29B through Hugging Face and APIs
Accessing Xing4.0 29B A4B requires either a local environment capable of hosting its 29B parameters or a connection to a provider.
The provider must support the specific Mixture-of-Experts (MoE) architecture developed by China Telecom Artificial Intelligence Technology Co., Ltd..
While the model only activates 4B parameters per token, the full 29B parameter weights must reside in memory.
Local deployment hardware requirements
Running this model locally necessitates a hardware configuration that can accommodate the full parameter set in Video Random Access Memory (VRAM) to maintain the efficiency gains of the MoE design.
You will need sufficient system RAM for the initial model loading phase so that the operating system doesn't bottleneck the transfer to the GPU.
- A GPU with sufficient VRAM is required so that the entire model fits without offloading to slower system RAM.
This means you only pay the compute cost of a small model per token while retaining the knowledge base of a much larger system.
API providers and inference endpoints
If you can't meet the local hardware threshold, you can utilize managed endpoints that handle the orchestration of the 4B activated parameters. The following providers offer compatible environments:
Hugging Face Inference Endpoints hosts dedicated instances so that you can maintain private data silos. The model was trained entirely on the Ascend NPU platform using the MindSpore framework.
When you need to manage the visibility of these integrations, versioning tools track deployment health. The version history interface displays the status of specific flow iterations, such as a green indicator for a stable webhook-to-code deployment or a yellow warning for a pending configuration change.
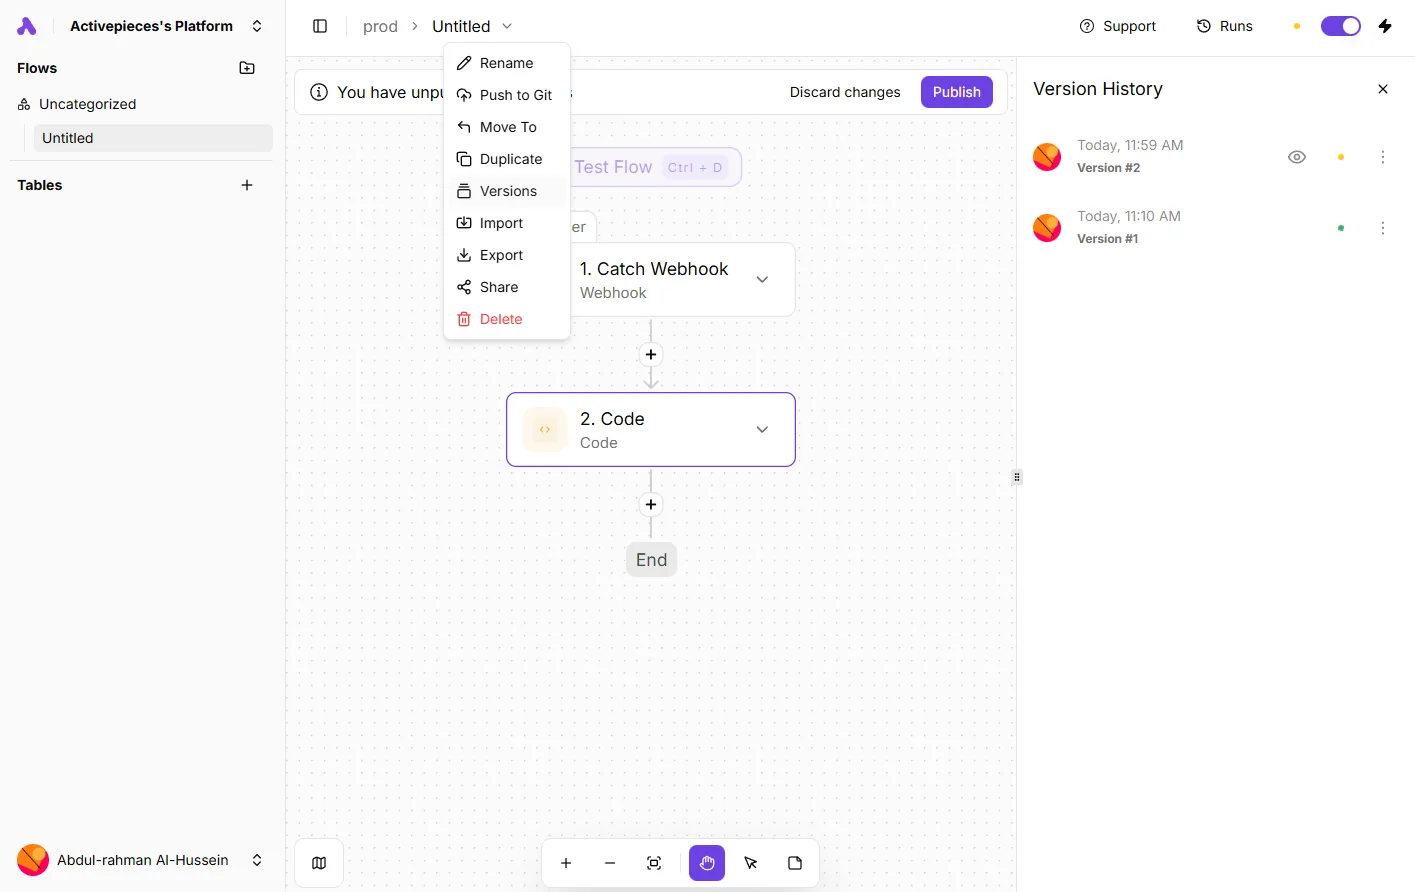
This allows you to rollback to a known stable state if a new inference endpoint fails to respond.
Xing4.0 29B Apache 2.0 licensing terms
This grants you the right to modify and distribute the software without paying royalties. This specific license is the only tier offered by the developers that permits commercial integration without a per-seat subscription fee.
Because the license is permissive, you can build proprietary wrappers around the 29B parameter backbone for your specific implementation.
Easier to see it running than to read about it: set it up free, no card.
How to implement Xing4.0 29B workflows
Integrating through the Model Context Protocol, which is an open standard for secure app-to-model communication, enables the system to safely fetch real-time data from external enterprise systems. The protocol establishes a standardized client-server architecture where the model acts as the client requesting specific context.
By exposing local databases and APIs through an MCP server, developers grant the model secure access to live operational metrics without exposing the underlying infrastructure.
To execute a data retrieval workflow, the model evaluates the user prompt and identifies the necessary tools defined in the MCP schema. It then generates a structured request that the protocol translates into precise API calls or database queries.
The server processes these actions and returns the relevant data payload directly into the model's context window for immediate analysis.
Strengths and limitations of the XingChen-AGI framework
The XingChen-AGI framework has the analytical depth of a high-parameter system but keeps the operational footprint of a much smaller model through its aggressive Mixture-of-Experts (MoE) architecture.
By activating only a fraction of its total parameters during a single inference pass, the system reduces the memory bandwidth required per token.
The sandbox is not the problem; the hardware is. This lowers per-token compute compared with a monolithic 29B alternative, but you still need hardware that can hold the full 29B weights.
Furthermore, this efficiency doesn't come at the cost of working memory. The native support for a large context window ensures that the model can ingest entire technical manuals or codebases without the information loss associated with aggressive vector database chunking.
The following table summarizes the core operational tradeoffs found within the current documentation:
| Capability | Status |
|---|---|
| Reasoning Density | High (4B Active) |
| Context Handling | 256K Native |
| Multilingual Support | Limited (Gaps identified) |
Prices and plan limits checked against huggingface.co and huggingface.co and docs.claude.com and openai.com and gemini.google on September 29, 2026.
What Activepieces does about this
To capitalize on the sparse efficiency of Xing4.0 29B A4B, users must bridge the gap between the model's reasoning and the enterprise data it needs to act upon.
The platform addresses the complexity of tool-augmented reasoning by exposing integrations as structured tools.
Because Activepieces ensures every connector is an agent tool by exposing its integrations through a per-project MCP server, developers can instantly equip their AI agents with a vast library of external capabilities.
This eliminates the need for manual schema mapping, as the model can query the Activepieces catalog to understand exactly how to format a request for specialized enterprise software.
For teams managing the 256,000 token context window, Activepieces can be used to feed data into the model.
Whether pulling multi-year financial ledgers from a database or entire repositories from a version control system, the platform handles the ingestion and pre-processing steps necessary to fill that window without manual intervention.
This allows the Xing4.0 29B model to focus its specialized experts on analysis rather than data retrieval logistics.
Operational stability is maintained through the platform's robust versioning and error-handling features.
This visibility ensures that as you scale your sparse model infrastructure, the automated workflows surrounding it remain predictable and auditable.
Frequently asked questions about Xing4.0 29B
Can I fine-tune Xing4.0 29B on a consumer GPU?
Fine-tuning this model requires a high-end consumer graphics card.
It must be equipped with sufficient VRAM, such as the NVIDIA GeForce RTX 4090, to accommodate the parameter count during the training process, which means users without high-end hardware will be unable to run the model locally.
If you rely on standard consumer hardware, you must utilize Parameter-Efficient Fine-Tuning (PEFT) techniques like QLoRA to reduce memory overhead. A full-parameter update would exceed the memory capacity of a single non-enterprise card.
Is there a smaller version of the Xing4.0 model?
If you're seeking a lower resource footprint, you'll typically deploy quantized versions of the 29B parameter model to reduce the memory required for inference.
If you require a natively smaller model for edge deployment or high-velocity tasks, you have several alternatives.
Ministral 3 3B from Mistral is a compact text and vision solution for mobile environments. Gemini 3.5 Flash-Lite from Google is a high-speed option for budget-sensitive multimodal workloads. GPT-6 Luna from OpenAI is designed to handle high-volume tasks with greater efficiency than the flagship series.
Does Xing4.0 support function calling natively?
Native function calling is a core feature of the Xing4.0 29B architecture, allowing the model to generate structured JSON outputs that map directly to external API definitions.
By using this native support, you ensure that you don't need to rely on brittle regular expression parsing to extract intent, which reduces the failure rate when the model interacts with external software tools.
Enterprise workflows requiring specialized reasoning for tool use often compare it against GPT-Realtime-2.1. This is a model from OpenAI specifically optimized for complex tool-augmented agentic tasks.