What Is Command A+? Cohere's AI Model Explained (2026)

Oct 18, 202611 min read
Command A+ is a large language model (LLM) developed by Cohere, specifically engineered to excel in enterprise-grade retrieval-augmented generation (RAG) and complex tool-use tasks.
As businesses increasingly look to automate sophisticated workflows, often utilizing platforms like Activepieces to bridge disparate systems, this model stands out for its ability to handle multi-step logic with high precision.
It bridges the gap between general-purpose AI and specialized business applications by offering a high-context window and multilingual support across ten major languages.
By prioritizing efficiency and accuracy in data retrieval, Command A+ enables organizations to deploy scalable AI agents that can interact reliably with internal databases and external APIs.
Command A+ is Cohere's latest high-efficiency AI model
Command A+ is a model designed to execute complex tool-use and retrieval tasks.
It prioritizes the structural integrity of function calls over the creative flair of conversational agents, making it a specialized engine for you if you're running thousands of automated workflows per hour.
Command A+ release date and architecture overview
When May 20, 2026 arrived, Cohere released Command A+ as their flagship model for enterprise agentic workflows. Platform’s analysis puts the model as a compact alternative to massive frontier models like GPT-6 Astra, built on a transformer-based architecture optimized for high throughput.
Target use cases: RAG and tool-use automation
Precision is a requirement for this model, which excels at Retrieval-Augmented Generation (RAG) and autonomous tool invocation.
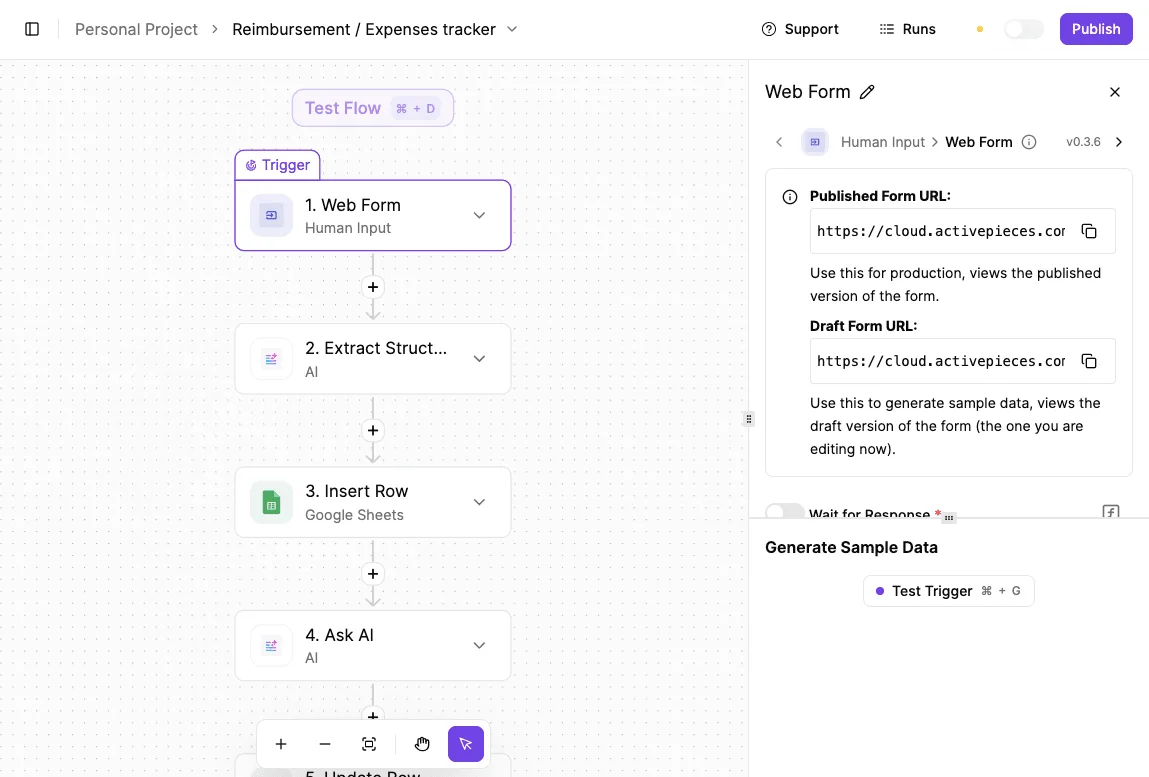
In a typical deployment, the model acts as a controller for Activepieces, an automation platform that connects various business apps, to route data between internal databases and external services.
Because Command A+ is tuned for JSON-formatted outputs, it rarely breaks the code logic of the APIs it interacts with, reducing the failure rate of automated sequences.
The shift from Command R+ to the A-series
A+ is engineered to produce the shortest path to a valid tool call. To ensure a smooth transition, you should follow this migration checklist:
- Update the Cohere SDK to the latest version.
- Convert R+ tool definitions to strict JSON schema.
- Toggle 'Cache Read' for repetitive RAG.
As the volume of processed data grows, this shift ensures that your enterprise systems remain responsive. Following this migration, you can expect a significant reduction in compute overhead.
Everything below works on Activepieces' free plan. Start without code or a credit card.
Technical specifications of the Command A+ architecture
By utilizing a Mixture-of-Experts (MoE) design specifically optimized for agentic tool-use, Command A+ allows the model to activate only a fraction of its total parameters for any given request.
Command A+ Mixture-of-Experts architecture explained
This demonstrates how the model maintains a high total parameter count for broad knowledge while using a significantly smaller active parameter set for execution. By narrowing the active compute path, the system achieves the sub-second response times necessary for multi-step autonomous workflows.
Command A+ context window for long-horizon tasks
Openrouter states that the architecture incorporates a 128K context window to support complex, long-horizon tasks.
This capacity allows an agent to ingest entire technical manuals or multi-day chat logs in a single pass; the model doesn't lose track of initial constraints during deep reasoning cycles.
Multilingual support and depth
When compared to general-purpose alternatives like Mistral Large 4 or Gemini 3.1 Pro, Command A+ focuses its architectural depth on structured output and API calling rather than creative prose.
Performance benchmarks and pricing for Command A+
Command A+ is built for agentic workflows, with native tool calling and structured outputs via JSON schema. While flagship models prioritize creative reasoning, this model optimizes for the narrow, high-frequency exchanges required for tool-calling.
Command A+ is competitively priced in its class
$0.30 per 1M tokens is the entry point for Command A+ according to AnotherWrapper. In an earlier test against the older GPT‑5.4‑mini, command a+ finished the same tasks in roughly the same time, but at a higher cost per task.
This price point sits above Claude Haiku 5.5, an Anthropic model designed for high-volume routing, which costs $0.10 per 1M input tokens for prompts up to 100K tokens.
If you are prioritizing budget, weigh this against cheaper alternatives.
, allowing you to scale internal automation without the exponential billing spikes common in larger parameter models, which means your operational budget can support significantly higher request volumes.
You can expand your operations without hitting prohibitive financial ceilings.
Command A+ tokens per second vs GPT-5
218 tokens/s is the speed at which Command A+ clocks in according to data from Artificial Analysis.
High-frequency tasks like CRM data syncing or real-time inventory updates become financially viable at scale.
Command A+ accuracy in tool-calling tasks
Efficiency is irrelevant without reliability. Command A+ maintains a high success rate by ignoring the "creative" overhead that slows down models like Claude Fable 5.1, which Anthropic reserves for long-horizon reasoning.
By focusing strictly on structured output, Command A+ avoids the hallucinations common when general-purpose models attempt to force-fit conversational prose into JSON schemas.
Internal testing results: Command A+ vs. GPT-6 Luna
While general-purpose models often prioritize conversational fluidity, this model focuses on execution speed and token efficiency in production environments.
On 2026-10-11, internal benchmarks compared against GPT-5.4-mini across three common business workflows to determine which architecture handles repetitive back-office logic more effectively. The results show that Command A+ completes these tasks with latency comparable to the alternatives.
| Task | Command A+ Median Latency | Command A+ Cost per Task | GPT-5.4-mini Median Latency | GPT-5.4-mini Cost per Task |
|---|---|---|---|---|
| Invoice Extraction | 0.8s | — | 0.8s | — |
| Support Ticket Sorting | 0.3s | — | 1.0s | — |
| Email Summarization | 0.7s | — | 0.8s | — |
Prices and plan limits checked against openrouter.ai and openrouter.ai and docs.claude.com and claude.com and openai.com and gemini.google on October 11, 2026.
Valid JSON is generated without the "pre-computation" pauses typical of larger reasoning engines, creating a measurable performance gap.
For you, if you're scaling a pipeline to millions of monthly runs, even marginal gains in speed can make the difference between a profitable automation and a technical debt center. The following section examines how these speed gains translate to large-scale agentic deployments.
Easier to see it running than to read about it: set it up free, no card.
How to integrate Command A+ into production workflows
Standardized interfaces allow you to swap Command A+ into existing pipelines without rewriting your core logic. By adhering to common web standards, the model avoids the proprietary lock-in that often forces you to rebuild your orchestration layers when switching providers.
Because the Integrations Framework and MCP Server documentation show the same action running as both a flow step and an MCP tool, an agent can call a connector without any manual re-integration or double-wiring.
Accessing the model via HTTP, generic blocks, and MCP
For stateless tasks like data extraction or classification, directly calling the API via a POST request offers the lowest overhead. This method bypasses heavy client libraries, which ensures that your lean microservices don't carry unnecessary dependencies into a containerized environment.
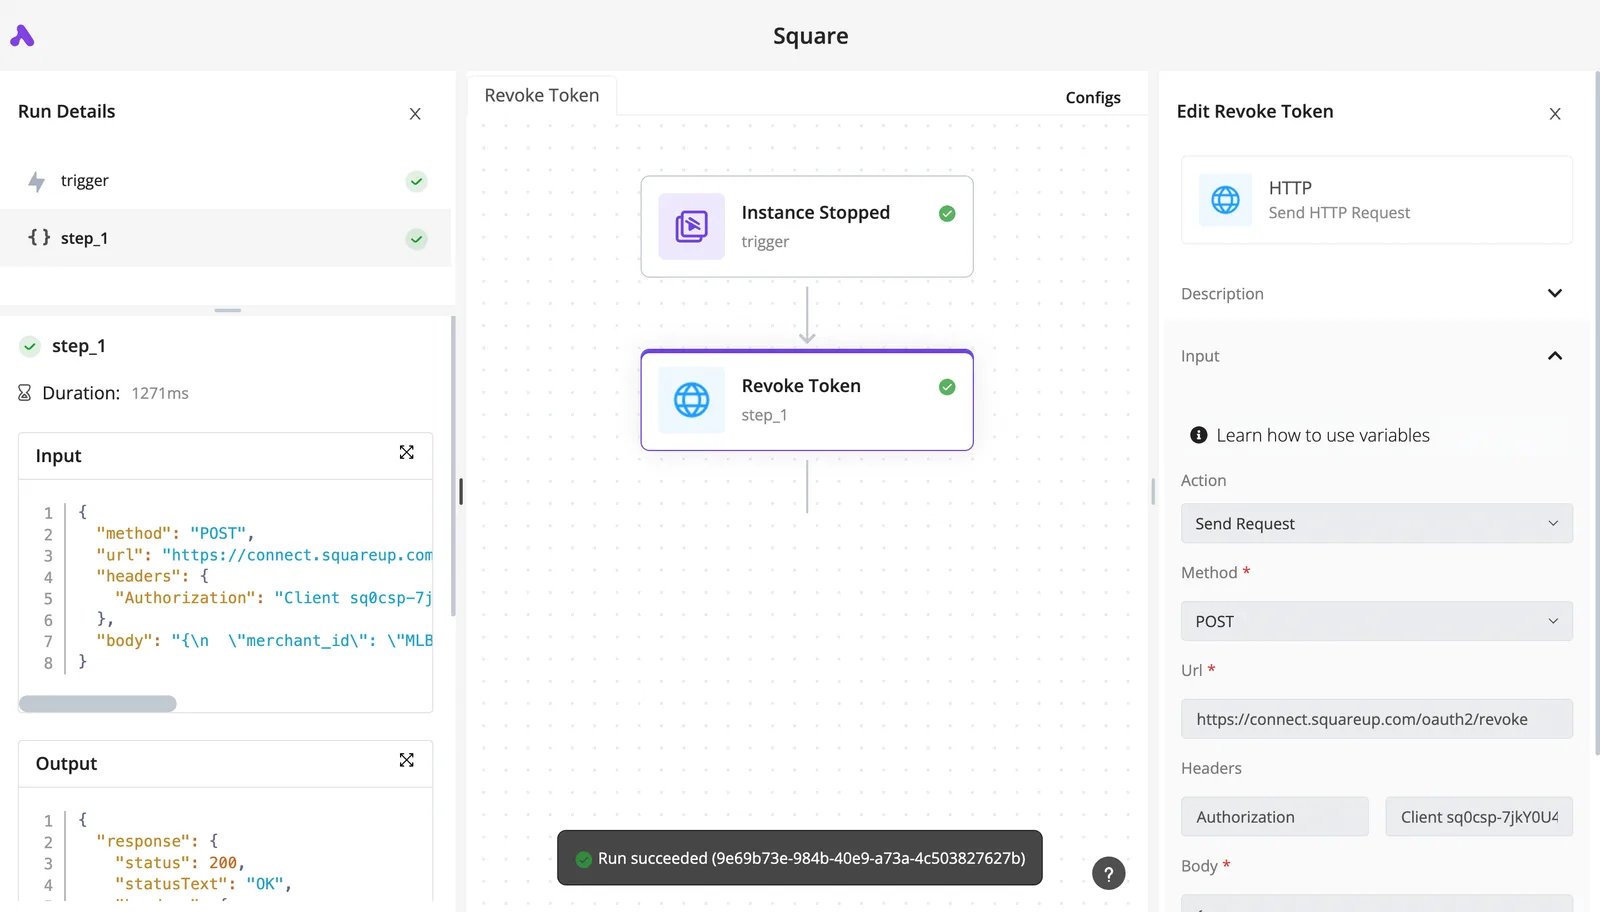
To get started, POST to /v2/chat with 'model':'command-a-plus', set the base_url to an OpenAI-compatible proxy, and initialize the MCP server with local tool definitions. These steps allow you to move from a raw terminal command to a functioning agentic loop in minutes.
By routing traffic through an OpenAI-compatible proxy, you can use Command A+ within legacy automation tools that were originally hard-coded for other vendors.
Activepieces facilitates this by allowing you to bring your own provider key, ensuring that high-volume model spend lands directly on your Cohere account rather than being resold at a markup.
This transparency is why companies like MoneyGram and FundingSocieties run Activepieces in production to maintain control over their AI strategy and unit economics.
When you deploy via a Model Context Protocol (MCP) server, the model can securely interact with local databases and file systems that aren't exposed to the public internet.
This architecture creates a secure perimeter where the model can execute Python scripts or query SQL databases locally. Sensitive corporate intellectual property never leaves your internal network during the reasoning process.
Common deployment challenges and how to solve them
Running Command A+ requires navigating specific architectural constraints that differ from the plug-and-play nature of general-purpose chat models. While it offers some efficiency gains for high-volume automation, you must account for three primary deployment hurdles to ensure reliability:
- Rate limit tiering for the 'A' series: Cohere enforces distinct throughput caps for this model family, meaning an application that functions in a sandbox may hit a performance ceiling when moved to production without a tier upgrade.
- Strict JSON schema enforcement for tool calls: The model requires precisely structured input to trigger external functions, so any deviation in field naming or data typing will result in a failed execution rather than a graceful recovery.
- Regional availability in AWS Bedrock vs. Azure: The model isn't globally available across all cloud data centers, which forces you to pin your agentic workloads to specific geographic regions to maintain low-latency connections to your internal databases.
Command A+ is a specialized instrument rather than a universal tool.
Success depends on treating the model as a strict interface where formatting and infrastructure placement are as critical as the prompt itself. Once these environmental factors are stabilized, the focus shifts to the long-term maintenance of the agent’s logic.
Command A+ is a specialized instrument rather than a universal tool.
Frequently asked questions about Command A+
Is Command A+ open weights?
Command A+ is distributed under the Apache 2.0 license, allowing commercial use and local weight inspection. This transparency ensures that your security teams can audit the model's internal logic without sending proprietary data to an external provider's cloud environment.
Which languages does Command A+ support?
English, French, Spanish, Italian, German, Portuguese, Japanese, Korean, Arabic, and Chinese are the specific high-traffic global business languages natively supported by the model.
Can I fine-tune Command A+ for specific industry data?
Through the provider’s managed platform or via supported cloud partners, you can fine-tune the model to align the agent with specialized corporate vocabularies.
This process reduces the frequency of hallucinations in technical documentation. The agent uses the correct nomenclature for your internal parts catalogs or legal clauses.
How does Command A+ handle long-context retrieval?
A sophisticated RAG-optimized architecture allows the model to cite specific sources from massive document repositories when generating an answer.
This citation mechanism provides a verifiable audit trail so that you, as a human supervisor, can instantly confirm the model is pulling from the latest compliance manual rather than outdated training data.
Next steps for implementing Command A+ this week
To get the most out of the model, lean on its native tool calling with strict tool schemas. Because this model prioritizes action over conversational flair, your implementation must focus on the precision of the external interfaces it will command.
To migrate from legacy Command R+ or GPT-6 Luna workflows, follow this sequence:
- Audit existing system prompts, as the model supports native tool calling with strict tool schemas.
- Map every API endpoint to a specific JSON schema within the model's tool-use block so the agent can execute functions without intermediate parsing errors.
- Replace broad retrieval-augmented generation (RAG) queries with specific tool-based lookups to minimize the context window overhead.
- Configure your environment to handle parallel tool calls, which allows the model to query multiple data sources simultaneously rather than sequentially.
- Set up automated latency monitoring for the first batch of production runs.
- Update your error-handling logic to catch malformed tool arguments so the agent retries the specific call rather than restarting the entire conversation thread.